Category: Uncategorized

  • Agency, Freelancer or Tools at €20k: How We’d Choose

    At €20,000 a month, distribution is no longer optional

    At €20,000 in monthly revenue, the business has already proved that somebody will pay for what it sells. The next constraint is usually discovery: too few of the right people know the company exists, understand its authority, or encounter it in the channels that shape buying decisions.

    The wrong response is to buy “content” as a production line. A pile of articles, social posts, or SEO tasks is not a distribution system. It only becomes one when someone owns the strategy, publishes consistently, measures discovery by channel, and improves what is already live. Visibility compounds; disconnected deliverables do not.

    Our view is direct: do not choose between an agency, a freelancer, or tools based on the cheapest monthly fee. Choose based on the bottleneck in the business. An agency buys breadth and coordination. A freelancer buys focused capability. Tools buy leverage for an operator who already has the time and judgment to use them. The cash cost matters, but founder time, reporting quality, and handover risk matter just as much.

    TL;DR: At this stage, the decision is really about who will own distribution discovery. Agencies are strongest when the work spans strategy, publishing, SEO, reporting, and channel coordination. Freelancers are strongest when the scope is narrow and someone internal can direct the work. Tools are strongest when an internal operator already knows what to measure, what to publish, and how to turn data from Search Console, Google Ads, Ads Manager, YouTube, the App Store, or Google Play into action.

    The real cost comparison: cash, founder time, and dependency

    The figures below are typical market ranges, not quotes. Some agency benchmarks are commonly stated in dollars, while revenue in this decision is framed in euros. Where possible, it is cleaner to compare the operating models with euro-denominated hourly benchmarks and then calculate what share of a €20,000 month each option consumes.

    Model Typical monthly cash cost What the founder still owns What breaks when the operator leaves
    Agency Typical small-to-mid-size content retainers: $2,000-$10,000. Typical B2B retainers: $5,000-$15,000. Business context, approvals, customer insight, strategic direction, and regular review calls. The team can be replaced internally by the agency, but switching agencies creates a strategy and onboarding reset.
    Freelancer Typical freelance content marketing rates: $50-$150 per hour, with mid-level work often at $50-$100 and experienced operators at $100-$150+. Editorial direction, channel strategy, analytics, prioritisation, and much of the coordination. One person’s knowledge, workflow, and capacity can disappear at once.
    Tool-led Typical stack: $100–$500 for SEO, content optimisation, and analytics subscriptions. Almost everything: research, planning, writing, editing, publishing, distribution, measurement, and iteration. The company keeps the subscriptions and data, but the incoming operator must reconstruct the system.

    A typical agency retainer in the $2,000–$6,000 band can represent a meaningful share of monthly revenue at this stage. That is a serious operating decision, not a line item to approve because a proposal contains a reassuring number of deliverables.

    The more useful comparison is this: tools are cheap in cash but expensive in execution time; freelancers can be cost-efficient but increase founder dependency; agencies reduce execution burden but can become expensive before the company has a clear distribution thesis. That comparison becomes clearer when you express the choice against the same €20,000 revenue base.

    A practical €20k/month view in euros

    For a side-by-side comparison, use one simple operating assumption: 160 billable hours in a month. At that level, €20,000 equals €125 per hour. If you prefer a leaner assumption of 140 hours, the ceiling is about €143 per hour. The point is not that every provider works hourly; it is that this gives you a comparable way to judge how much of a €20,000 month each model is likely to consume.

    Model Euro benchmark Approx. monthly cost at 160 hours Share of €20,000 revenue
    Freelancer European freelancer average around €103/hour, with broader specialist ranges around €60-€180/hour depending on field and seniority About €16,480 at the average; roughly €9,600-€28,800 across the broader range About 82.4% at the average; roughly 48%-144%
    Agency European agency benchmarks around €70-€135/hour, with a median around €105/hour About €11,200-€21,600; about €16,800 at the median About 56%-108%; about 84% at the median
    Mid-tier agency band Common B2B/SaaS agency range around €100-€149/hour About €16,000-€23,840 About 80%-119.2%
    Tool-led Software cash cost is usually far below labour cost; the real spend is internal operator time Cash outlay is often modest relative to staffing, but total cost rises fast once an internal operator is spending meaningful hours every week Cash-only share is usually low; total share depends on how much internal time is committed

    This is why the cheapest-looking option can be the most expensive one operationally. A founder who buys tools but then spends the equivalent of a part-time operator’s week inside them has still made a major distribution investment. Likewise, a freelancer or agency that looks expensive on paper may be efficient if it removes founder bottlenecks and produces a system the company can keep.

    Choose an agency when the work genuinely needs a team

    An agency is the right call when the company needs several functions working together: strategy, editorial planning, writing, design, SEO, publishing support, and reporting. That bundled capability is what the retainer buys. It is not simply a more expensive writer.

    Typical boutique retainers in the $3,000–$6,000 range often cover four to eight pieces of content each month. Typical mid-size agency retainers in the $6,000–$12,000 band often support eight to sixteen pieces. Those output figures are useful only if they are connected to a distribution plan: which buyer problem each page addresses, which channel will surface it, and what evidence will determine whether the work should be expanded, improved, redirected, or removed.

    That last point matters because discovery is broader than blog production. If your visibility problem spans search, paid acquisition, landing pages, remarketing, and reporting, an agency can coordinate across channels more easily than a solo operator. It is also the more realistic option when the company needs one system that joins Search Console, analytics, Google Ads, Ads Manager, CRM outcomes, and publishing workflow instead of treating each as a separate task.

    The mistake we see most often is hiring a full-service agency to compensate for an undefined internal strategy. That creates polished activity but weak ownership. The founder still needs to supply product context, customer language, priorities, approvals, and sharp feedback. Agency engagements commonly involve weekly or bi-weekly calls, plus asynchronous reviews. The agency can reduce execution time; it cannot eliminate the need for executive judgment.

    Do not pay an agency premium merely to receive a calendar of generic topics. Pay for an operating system that makes the company easier to discover and harder to ignore across more than one channel. Single-channel growth is fragile, particularly when a company is still building its authority.

    Choose a freelancer when the constraint is narrow and well defined

    A freelancer is usually the strongest value when the company already has someone internally who can set priorities and make decisions, but lacks a specific capability. That could be disciplined editorial production, SEO-led writing, campaign execution, or specialist channel knowledge.

    Typical freelance content marketing rates sit between $50 and $150 per hour. Mid-level work is commonly priced at $50–$100 per hour, while experienced operators often charge $100–$150+. The economics work best when you know exactly what you are buying: for example, a writer who can execute a search-led brief, a specialist who can improve YouTube titles and metadata, or a contractor who can clean up underperforming landing pages rather than invent the whole system from scratch.

    The headline fee can look attractive beside an agency retainer. The hidden cost is management. Without an account manager, strategist, designer, and analyst around the freelancer, the founder or small marketing team often becomes the editorial director, distribution lead, and performance reviewer. If the business has that capacity, this is efficient. If it does not, the freelancer becomes a producer waiting for instructions.

    This is also where discovery use case matters. A freelancer can be excellent when the problem is narrow: organic search content, App Store listing copy, Google Play metadata, competitor page analysis, email distribution, or a defined paid campaign. The model becomes weaker when the company needs cross-channel discovery management across website SEO, paid, social, app-store optimisation, and reporting at the same time.

    The other cost is concentration risk. A good freelancer can become deeply embedded in customer language, search intent, and the logic behind a content roadmap. If that person leaves, the business retains paid-for assets but can lose the operating knowledge behind them. Avoid that by requiring company-owned access, a visible editorial backlog, documented publishing standards, and monthly reporting that lives outside the freelancer’s private workspace.

    Choose tools only when somebody internally owns the work

    A tool-led approach is not a lower-cost agency. It is an in-house commitment. SEO, analytics, content optimisation, and planning platforms can reduce research time and make performance more visible. They do not decide which buyer problem matters, write credible expertise, publish pages, earn attention, or turn data into a distribution decision.

    A typical stack of one to three tools costs $100–$500 per month. That is materially lower than agency or freelancer spend, but it shifts the real bill into founder or team time. Tool-led programs often require three to ten hours each week for planning, drafting, optimisation, publishing, and performance review.

    Tools are most useful when they are matched to a specific discovery use case. If the problem is SEO gaps, use tools to compare topics, pages, and queries the market is already winning. If the problem is YouTube visibility, use them to monitor competitor publishing patterns and video discovery signals. If the problem is app discovery, the work is closer to ASO, or app store optimisation: watching how the product appears in the App Store on iOS and in Google Play, reviewing listing changes, and connecting that visibility to channels such as Apple Search Ads or paid acquisition.

    This is where software can genuinely help, but only if the operator knows what to do with it. Tools such as App Radar, Sensor Tower, Google Play Console, or SplitMetrics Optimize can support app-store discovery work; Search Console and broader SEO tooling can support website discovery; and paid interfaces such as Google Ads or Ads Manager can show how competitors frame offers and where your own message is underperforming. The software does not replace judgment. It narrows the search space so a human can make better decisions.

    This route works when there is a capable internal operator with protected time and authority to act. It fails when the company buys dashboards instead of building a cadence. A dashboard full of keyword positions, page metrics, or AI Mode observations is not progress if no pages are being improved, no distribution experiments are running, and no one can explain why a page exists.

    The advantage is audience and operational ownership. The company retains access to the data and subscriptions if a staff member leaves. The weakness is that the next operator still needs to understand the strategy, reporting logic, page inventory, and publishing workflow. Systems outperform manual effort only when the system is documented well enough to survive a personnel change.

    Our recommendation at this stage: buy accountable operating judgment

    At this revenue level, we would not default to a large full-service agency and we would not default to DIY tools. We would first establish a narrow, accountable visibility system: clear ownership, company-controlled data, a realistic publishing cadence, and reporting tied to discovery rather than content volume.

    For companies at €20,000 a month revenue or more, our own range is €1,500 to €5,000 a month. It sits between tool-only spending and broader agency retainers because the purpose is not to manufacture content at scale. The purpose is to create a durable discovery system the business can inspect, understand, and retain.

    What a serious operator shows every month

    Monthly reporting is where weak providers reveal themselves. A report that lists completed articles, ranking screenshots, or broad traffic totals is not enough. It tells the founder that activity occurred, not whether the company’s visibility is becoming an asset.

    A serious operator should show the same core view every month:

    • Clicks by channel: organic search, paid channels, email, social, app-store traffic where relevant, and other meaningful sources should be separated. A blended total conceals where discovery is strengthening or weakening.
    • Impressions: show the scale of opportunity and whether the company is appearing more often before a prospect clicks.
    • AI citations as a separate unit: citations are appearances or references in AI-generated answers. They are not clicks, sessions, or traffic, and they should never be added into click totals.
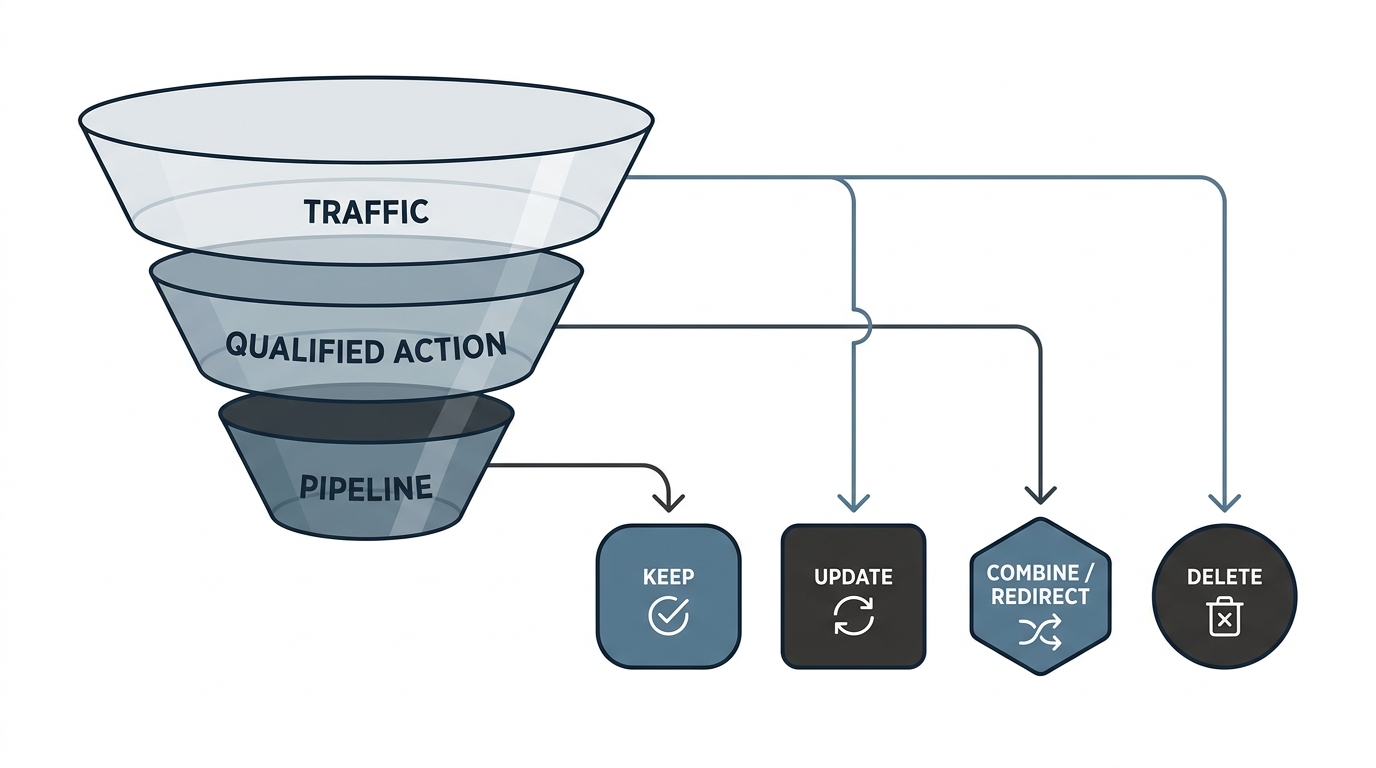
    • Pages added and removed: show new pages published, substantial updates completed, and pages removed or redirected. This is the operational record of how the site is changing.
    • Outcomes: show the relevant leads, signups, or conversions alongside the pages and channels contributing to them.
    • The next plan: explain the coming topics, distribution experiments, technical changes, and the reason each one deserves attention.

    This reporting standard matters because discovery is a business function. It lets a founder see whether the business is earning more visibility, building authority in the right subjects, and reducing dependence on a single acquisition channel.

    The due-diligence test before signing

    Use this exact question with any agency, freelancer, or consultant: “Show me a site you run and its Search Console.”

    A serious provider can walk through a real operating view, with identifying details redacted where necessary, and explain clicks by query, impressions, average positions, page performance, and coverage issues. The point is not to demand confidential client information. The point is to distinguish someone who has operated a live discovery system from someone who can only describe one.

    Before committing, require clarity on reporting cadence, metric definitions, treatment of AI citations, ownership of analytics access, page-change records, and handover expectations. If the provider leaves, the company should keep its pages, data access, measurement history, editorial logic, and operational documentation. Authority is an asset only when the business owns the system that creates it.

    The practical decision

    • Choose an agency when multi-disciplinary execution is the actual bottleneck and the company can fund a genuine distribution program.
    • Choose a freelancer when the scope is focused and someone internally can own strategy, decisions, and measurement.
    • Choose tools when an internal operator has protected time to turn data into publishing and distribution work.
    • Reject any provider that sells output without channel-level clicks, impressions, separate AI citation reporting, and a visible record of pages added and removed.
    • Build the work in company-owned systems from the beginning, so visibility compounds for the business rather than walking away with a vendor.

    At €20,000 a month, this is less a content purchase than an operating-model choice. The right answer depends on whether your real bottleneck is breadth, specialist execution, or internal ownership. Make the decision against discovery outcomes, reporting quality, and handover resilience, not against a comforting list of deliverables.
  • Product or Distribution Problem? A 5-Minute Game Review Test

    Most companies that say “we need more marketing” are not describing a marketing problem. They are describing uncertainty. In mobile games, that uncertainty often shows up first in App Store and Google Play reviews: the team sees a slide in ratings, a wave of complaints, or a burst of praise that does not translate into retention, and still cannot tell whether the bottleneck is the product, the monetization design, the message, or the lack of a reliable way to get seen.

    Across the businesses we have observed, this uncertainty becomes expensive fast. Teams react by buying more user acquisition before the game earns repeat attention. Or they retreat into product work when the real issue is that almost nobody is discovering the listing, the update, or the event. Both moves feel productive. Both can waste a quarter.

    There is a faster way to separate the two. It is not a complete growth strategy, and it is not a declaration of product-market fit. It is a five-minute diagnostic that forces an honest next decision. In mobile, the smartest version of that diagnostic is tied to a real review-management workflow, because reviews are where product pull, monetization friction, support debt, and discoverability confusion all collide in public.

    Use two signals, not a dashboard full of excuses

    The test is built on two questions. The first tests product pull. The second tests distribution presence.

    • Did the last 20 people you personally showed it to come back on their own?
    • Does any channel bring at least a few hundred impressions a week without you actively pushing it?

    The answers are not meant to flatter the founder or the game team. They are meant to stop the wrong kind of work.

    Return behavior matters more than praise. A player, partner, creator, or prospect can tell a team that the game is polished, interesting, or “has potential” and still never open it again. That is politeness, not pull. A return visit, a follow-up session, a reinstall after a test, a player who comes back after a patch, or a user who voluntarily tries the feature again says something more valuable: the experience created enough unresolved value that the person chose to spend attention on it again.

    The impressions test matters because a good product cannot compound in a vacuum. A game does not need massive reach to prove it has distribution. It needs evidence that a channel is producing ambient discovery without the team manually creating every interaction. Store search, featuring momentum, recurring creator mentions, community referrals, or a useful store asset that keeps getting found can all qualify. The channel matters less than the pattern: visibility continues when manual pushing pauses.

    That is where review operations become more than customer service. If your review flow is messy, you will misread both signals. A bug spike can look like a marketing problem. A monetization complaint can be mistaken for a product-wide rejection. Fraud cases can pollute your understanding of sentiment. Before a team argues about product versus distribution, it needs a clean operating system for what players are actually saying.

    Key takeaways

    • Returning after a direct exposure is a stronger product signal than compliments, community enthusiasm, or a polite promise to follow up.
    • A few hundred organic impressions a week is not scale. It is proof that some form of discovery exists without constant team effort.
    • Product pull and distribution strength are separate variables. Treating one as proof of the other causes bad decisions.
    • For mobile game teams, review management works best as a five-step lifecycle: collect, tag, route, reply, and learn.
    • Each outcome requires one dominant action. Mixing product rebuilding, review triage, and channel expansion at the same time usually creates noise, not learning.

    The 20-people test exposes whether attention is earned

    The last 20 people test is deliberately small. Teams often delay judgment until they have more installs, more reviews, more survey responses, or a cleaner reporting stack. That instinct is understandable and usually wrong. Small groups are enough to expose patterns when the observation is behavioral and the audience is the right one.

    The point is not to assemble 20 random acquaintances, collect generic feedback, and call the exercise validation. The point is to look at the last 20 relevant people who received a real view of the game or the monetization loop: a soft-launch player, a reactivation cohort, a creator preview, a live-ops participant, a store visitor who reached the listing, or a player who contacted support after trying to buy something.

    Then remove the team’s follow-up from the equation. Did they return without a reminder? Did they reopen the game after the tutorial? Did they try the event again after the first session? Did they complain about a specific pain point and then continue playing anyway? Did they bring sharper feedback the second time? Those behaviors indicate that the experience has started doing some of the selling itself.

    This distinction is especially important in mobile games because operations can disguise a weak product. A community manager can carry a frustrated conversation with empathy. A support lead can defuse a billing complaint. A growth lead can create a short-term traffic burst. None of that means the core loop, the economy, or the value proposition is strong enough to earn repeat attention once the conversation ends.

    We see this most clearly in games that solve a legitimate entertainment need but not in a compelling enough way. The store page looks sharp. The first session lands reasonably well. The player agrees the concept is appealing. Then nothing happens. No return. No event participation. No sign that the game has become part of a habit. That is not a distribution failure. More impressions would simply create more first sessions followed by silence.

    There is a useful operational lesson in mobile review management. The strongest systems do not treat feedback as a pile of comments. They collect it, tag it, route it, reply to it, and learn from it. Product teams should treat founder-led or operator-led discovery the same way. Capture what happened after each direct exposure. Tag the reason for return or non-return. Route recurring friction to the owner who can fix it. Learn from behavior rather than collecting another round of flattering quotes.

    In practice, the tagging matters because not every negative reaction means the same thing. A complaint about bugs is different from a complaint about balance. A complaint about pricing is different from a billing failure. A player asking for a feature is not rejecting the game; they are describing what would make the game stickier for them. If the team throws every low rating into one “negative feedback” bucket, the 20-people test becomes muddy when it should be clarifying.

    The impressions test exposes whether discovery exists without you

    The second question is intentionally modest: does any channel generate a few hundred impressions a week without active pushing?

    That threshold is not a growth trophy. It is a distribution floor. It tells a mobile team whether the company has any repeatable surface through which players can discover the game when nobody is manually nudging every post, creator outreach thread, update announcement, or community prompt.

    Teams routinely confuse activity with distribution. Publishing patch notes is activity. Running a burst campaign is activity. Posting clips is activity. A channel that keeps creating qualified exposure after the activity ends is distribution.

    A practical example makes the difference clear. A team might publish smart event updates whenever retention looks soft. The updates receive attention only when the team spends time cross-posting them, answering comments, nudging creators, and pushing community traffic back to the store listing. The moment that work stops, visibility disappears. That is not a channel yet. It is manual promotion with a content wrapper.

    By contrast, a store presence that keeps surfacing in search, a creator relationship that repeatedly drives interest, a recognizable game hook, or a review-response pattern that improves store trust creates an asset. It may not produce enough demand to hit the company’s revenue target. It does prove that discovery can happen without a fresh push every day.

    This is also why collecting reviews into one place matters. A setup such as AppFollow’s Reviews and Ratings dashboard can become the collection layer after connecting App Store Connect and Google Play Console, so reviews land in a single queue rather than multiple native consoles. That does not create distribution by itself, but it gives the team one view of how discovery and post-install experience interact across stores, versions, languages, and markets.

    Once that queue exists, the useful work begins. Tag each review by sentiment—positive, neutral, or negative—and by topic such as bug, balance, monetization, fraud, praise, or feature request. Then route it by app, language, severity, or topic. That is how a visibility question stops being abstract. If one market is discovering the game but server-outage complaints dominate there, the issue is not “marketing.” If impressions are weak but praise clusters around a specific feature, the issue may be packaging and discoverability rather than core enjoyment.

    The four outcomes — and the one move for each

    The value of the test is not in producing a perfect diagnosis. Its value is in making the next move obvious. There are four possible outcomes.

    Outcome What it means One action
    Yes / Yes The product earns return attention and a channel already creates discovery. Action: Scale the working channel while tightening the message around the behavior that brings people back.
    Yes / No The product can hold attention, but the company has no dependable way to create enough first exposures. Action: Build distribution intentionally around one channel that can become an owned, repeatable asset.
    No / Yes The company is getting seen, but the product or offer is not earning a second look. Action: Fix the product experience, offer, or positioning before increasing reach.
    No / No Neither the product nor the distribution system has produced a meaningful signal. Action: Stop scaling activity and rebuild the offer, the positioning, or both.

    For game teams, these quadrants become more practical when attached to review workflows. The raw queue tells you what people felt. The tags tell you why. The routing tells you who owns the fix. The replies tell players that someone is listening. The learning loop tells the business whether the next patch, price change, or store update actually changed behavior.

    Yes on both: scale what already has proof

    This is the only quadrant where acceleration is justified. The game earns repeat interest and a channel creates ongoing exposure. The mistake here is expanding into every available channel because the team finally has momentum.

    Do not dilute the signal. Scale the channel that is already working and make the message more explicit about the behavior that drives return. If players come back because the game resolves a session quickly and cleanly, the store message should own that. If they return because the meta progression feels satisfying, highlight that. If praise clusters around an event format or a system like a Battle Pass, that is useful language for positioning, not just a compliment to file away.

    This is where review management can help marketing rather than distract from it. Positive praise should not simply receive a thank-you and disappear. It should be tagged as praise, clustered against other positive reviews, and fed back into product marketing and app store optimization. One template library for mobile game reviews covers eight common review types—positive praise, gameplay complaint, balance patch complaint, IAP or monetization grievance, bug report, server outage or connectivity issue, feature request, and fraud or chargeback or account issues—and together those categories cover roughly nine in ten game reviews across the App Store and Google Play. When a team knows which positive themes recur, it can scale the message with less guesswork.

    Yes on product, no on distribution: stop waiting for magic

    This is where the “great products market themselves” myth does the most damage. Good games do not market themselves. They retain attention once somebody encounters them. Those are different jobs.

    If direct exposure produces return behavior but no channel delivers a few hundred organic impressions a week, the company has a distribution problem. The response is not to keep polishing features in the hope that visibility will somehow appear. It is to choose a discoverable channel, commit to it long enough to build a system, and create assets that outlive the team’s daily effort.

    The key word is intentionally. A distribution system needs a repeatable input, a recognizable message, a capture mechanism, and a way to learn what turns exposure into installs and repeat play. Review workflows help here too. When reviews praise the art style but complain about the store promise, that suggests a packaging issue. When one language market produces strong sentiment and another produces confusion, routing by language or market can expose a discoverability problem that a blended global average would hide.

    Replying well matters, but only when it is part of a system. AI-assisted drafting can help a team move faster, yet the safer pattern is approval mode: the AI reply assistant drafts, and the community manager edits and approves before anything is published to the store listing. That keeps the reply process efficient without turning the public review thread into autopilot. In one Joyteractive example, this kind of workflow is described as reaching a 91% reply rate, cutting typical reply time to about 55 minutes, and removing roughly 35 hours of manual work per month. The point is not the specific benchmark. The point is that disciplined review operations can free time to build actual distribution.

    No on product, yes on distribution: do not pour fuel on a weak offer

    This quadrant hurts because it often looks like progress. The game has impressions. It has listing traffic. It may even have install volume. Yet players do not return after getting a proper look.

    The bad response is to blame icon tests, demand more creator coverage, or buy additional reach. More distribution will make the problem more visible, but it will not solve it. This is the moment to examine the actual experience: the promise being made, the speed to value, the first-session friction, the economy, the patch impact, or the gap between the store claim and the product reality.

    Review tagging makes that diagnosis concrete. If negative reviews cluster around bugs, route them to engineering. If they cluster around balance after a patch, route them to design or LiveOps. If they cluster around monetization, separate pricing and value feedback from purchase and billing problems. That distinction matters. A player saying “this bundle feels bad” is giving economy feedback. A player saying “I paid and did not receive the item” has a support issue. Those should not be answered by the same owner or with the same template.

    The IAP workflow should be equally disciplined. Monetization complaints can be tagged as Sentiment: Negative and Topic: Monetization, while billing issues go to support rather than becoming open-ended public debates. The right move is still the same: fix the offer before scaling exposure. Until players return on their own, growth spending is simply an expensive way to collect rejection at scale.

    No on both: this is not a marketing emergency

    No return pull and no organic discovery is the quadrant teams most want to explain away. They point to a crowded category, a slow season, weak brand awareness, or the need for one more event. Sometimes those factors are real. They still do not alter the operating decision.

    Stop scaling. The company has not earned the right to pour more resources into promotion, nor has it found an experience players want to revisit. Rebuild the offer, the positioning, or both. That might mean narrowing the target player, changing the first-session experience, clarifying the store promise, or making the value proposition painfully concrete.

    This is also the quadrant where fraud and account issues can distort judgment if the team is careless. Fraud, chargeback, and account-issue cases should move to a secure support channel rather than being “resolved” in a public review thread. The right tag for that workflow is Sentiment: Negative and Topic: Fraud, and the reply should direct the player to a security support path while keeping account details private. If clusters of near-identical 1-star reviews suddenly appear in a much shorter window than typical—for example, the same phrase showing up more times in one day than it usually does in a week—the team should stop replying one by one and investigate. Not every negative wave is product truth. Some of it is operational noise, abuse, or coordinated behavior.

    This is not failure. It is useful clarity. The expensive failure is maintaining the fiction that more output will compensate for the absence of pull and the absence of distribution.

    The mistake is treating product and distribution as competing explanations

    Founders and game teams often frame the argument as a choice. Either the game is good and marketing is unnecessary, or the game is fine and distribution is the only thing that matters. Both camps are wrong because they treat two linked systems as substitutes.

    Product pull determines what happens after attention arrives. Distribution determines whether attention arrives often enough for the business to learn and grow. One cannot permanently compensate for the other.

    In mobile, the cleanest bridge between the two is review management. Collect reviews from the App Store and Google Play into one workspace. Tag them by sentiment and topic. Route them by app, language, severity, or owner. Reply with approved templates and human oversight. Then learn from the patterns by version, market, and theme. That five-step lifecycle—collect, tag, route, reply, learn—is not busywork. It is an operating system for seeing whether your game has a product problem, a distribution problem, or both.

    The five-minute part is the diagnostic, not the whole job. A fast triage can tell you where to look. The workflow is what prevents the team from having the same argument again next week.

    The takeaway

    Use the last 20 people test and the few hundred impressions test before approving the next user-acquisition burst, store-page rewrite, or growth hire, then run the answer through a real review workflow.

    If people return and no channel carries reach, build distribution. If a channel creates reach and people do not return, fix the product. If both signals are present, scale the system already earning attention. If neither exists, rebuild before spending more.

    That is the discipline: stop arguing about whether the business has a product problem or a distribution problem. Measure both, then collect, tag, route, reply, and learn from what players tell you in public.

  • How to Get Cited by ChatGPT and Perplexity

    The homepage is usually the wrong page to optimise for AI citations. It may explain what your company does, but it rarely gives ChatGPT or Perplexity a precise claim to support. The pages that earn citations answer one specific question, make a clear claim, and provide enough evidence for an AI system to use that claim without rewriting or guessing.

    This matters because a brand can be absent from AI answers long before it notices a traffic problem. A prospective buyer can ask for a comparison, an implementation approach, a definition, or a recommendation inside ChatGPT or Perplexity and receive an answer that omits your company entirely — or represents it inaccurately. That is a discovery problem, not merely an SEO problem.

    Our recommendation is to treat AI citation as a visibility system. Start by tracking the prompts that matter to your buyers. Then build focused, evidence-led pages that answer the missing sub-questions those prompts create. Finally, measure citations separately from visits. Distribution beats content when the content is deliberately built to be found, extracted, and reused in the places where buyers now form opinions.

    TL;DR

    • An AI citation is an AI answer that names or links a specific page; it is not a visit.
    • Homepages and vague overviews rarely get cited because they do not support a precise claim.
    • Pages that answer one specific question with a clear source are far more useful to ChatGPT and Perplexity.
    • Track buyer prompts first, then publish narrow, evidence-led pages to fill the gaps.
    • Measure citations and clicks separately, because citations and clicks are separate units.

    First, use the right unit: a citation is not traffic

    An AI citation is an AI answer that names or links a specific page. It is not a visit, a click, a search impression, or an analytics session. A citation exists when the AI interface visibly shows your page title, domain, or URL in a source list or inline reference.

    That distinction is not academic. On FinalBoss, our own portfolio property, we recorded 586,940 AI citations over 18 months. In June 2026, FinalBoss received 112,585 AI citations next to 3,874 Google clicks. Those are different units from the same month. Citations and clicks are separate units. They should sit next to each other in reporting, never be added together.

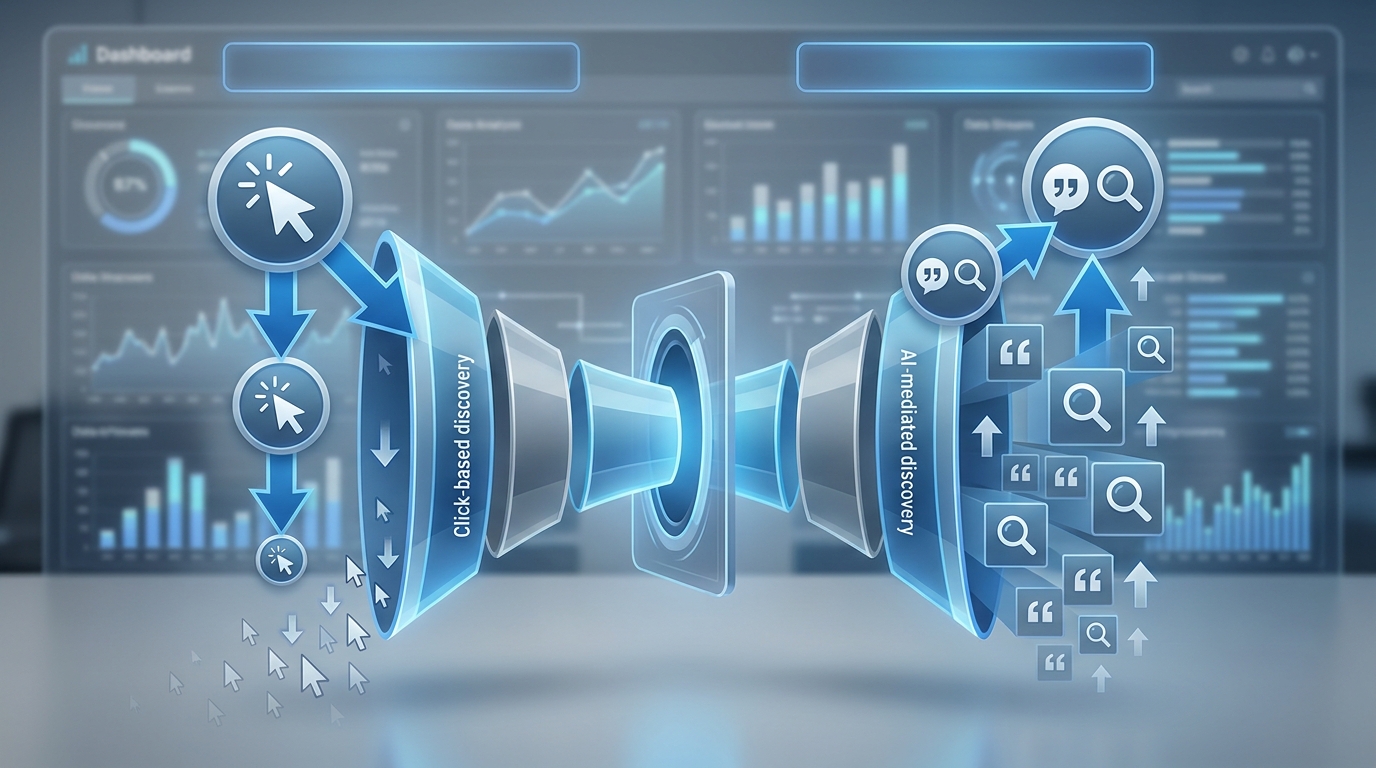
    The citations tell us that pages were selected as sources inside AI answers. The Google clicks tell us that people visited through Google. Neither number substitutes for the other. Citation growth can mean your company is becoming more visible in AI-mediated research, while browser visits remain unchanged because the user read the synthesized answer and never left the interface.

    Do not call citations traffic. Doing so creates a flattering dashboard and bad decisions. Treat citations as a measure of AI visibility and source selection. Treat clicks as a measure of navigation. Then investigate whether greater visibility improves branded demand, sales conversations, direct visits, or qualified pipeline over time.

    That reporting discipline changes strategy. If a team thinks a citation is the same as a click, it will optimise for the wrong outcome and misread progress. If it understands that a citation is a source-selection event inside an AI answer, it can ask a more useful question: which pages are trusted enough to be reused when buyers are comparing options, learning a category, or checking how something works?

    What ChatGPT and Perplexity are actually looking for

    Perplexity does not need a perfect page for every full query. It can break a broad request into narrower retrieval needs, find pages that address those pieces, then synthesize an answer from several sources. ChatGPT’s web-enabled answers similarly need accessible documents that directly support the statements they make.

    That is why broad positioning pages lose. “The complete platform for modern teams” is useful sales language but weak source material. It gives an AI little to cite beyond a generic company description. A page that explains a single mechanism, constraint, comparison, or decision is much more useful because the system can attach it to a specific part of an answer.

    The pattern is consistent: pages that answer one specific question with a clear source get cited; homepages and vague overviews do not. The winning page is not necessarily the longest page. It is the page with the cleanest match between a user’s question, a defensible answer, and evidence that makes the answer safe to reuse.

    Retrieved is not the same as cited

    This is the part many teams miss. A page can be accessible enough to enter retrieval and still fail to become a citation. Retrieval means the system found the page as a possible source. Citation means the system decided that the page directly supported the final answer strongly enough to name or link it.

    Perplexity’s workflow helps explain the difference. It can decompose a prompt into narrower sub-queries, retrieve candidate pages, filter them by topical match, read relevant passages, rerank those passages, then synthesize an answer with source attribution. In practice, that means a page can be relevant at the top of the process but lose at the end because it is too vague, too stale, too hard to quote cleanly, or too thin on evidence.

    The same practical logic applies to ChatGPT when web-enabled browsing is involved. Being indexed is not enough. The page still has to provide a direct, extractable answer. If the model can understand your page but cannot confidently attach one passage to one claim, another source will usually do the job better.

    Build for extractability, not applause

    Most content teams still publish for the imagined human who reads from top to bottom. AI retrieval systems work differently. They need to identify a relevant page, locate a passage, verify that it supports the prompt, and place that passage beside claims from other sources.

    A source-ready page makes this easy. Its title, main heading, opening paragraph, section headings, and supporting facts all agree on the same narrow subject. It does not bury the answer below a brand story, an oversized product pitch, or a wall of opinion.

    For a B2B SaaS company, the difference is straightforward. A general feature page might say that the product helps revenue teams work more efficiently. A citation-ready page would answer a focused issue such as how a revenue team can handle a defined operational constraint, what the workflow includes, where the limits are, and what evidence supports the explanation. The second page gives an AI system a usable source. The first gives it marketing copy.

    Extractability is not a stylistic preference. It is a distribution requirement. Clean headings, short paragraphs, clear labels, direct definitions, and visible supporting facts give the model less room to guess. That is exactly what you want if the goal is to be cited accurately rather than merely mentioned loosely.

    How we would approach AI citation visibility

    We would not begin by publishing a larger volume of generic AI content. That compounds inventory, not authority. We would begin with prompt tracking: a disciplined view of the questions buyers ask AI systems before they know your brand, while they compare approaches, and when they are deciding whether a product can solve a specific problem.

    The practical process is Prompt map → missing source page → evidence-led answer → citation review. The point is not to reverse-engineer a secret ranking formula. The point is to identify where your brand is invisible, underrepresented, or incorrectly framed, then give the model a better page to retrieve.

    That framing also makes the work manageable for a small team. You do not need a sprawling AI-content programme. You need a shortlist of prompts tied to real commercial decisions, a way to inspect the answers those prompts produce, and a publishing discipline that turns repeated gaps into durable source pages.

    Map the questions behind commercial intent

    Start with the questions that appear before a sales conversation, not only branded queries. Buyers often ask AI systems to explain a category, compare methods, diagnose a problem, identify constraints, or choose between product types. These prompts influence which companies enter the consideration set.

    Group prompts by the decision they support. One group may concern implementation. Another may concern integrations, security, operational fit, pricing logic, migration risk, or the trade-offs between doing something manually and using software. This is the real content strategy: a map of decision-critical questions, not a calendar of topics.

    Then record the answer quality. Is your company named? Is a competitor named instead? Does the answer repeat an outdated claim? Does it cite a weak third-party description because you have no primary page that explains the issue clearly? Each gap points to a page or proof asset your business needs to own.

    This is where many teams discover the real problem is not lack of content but lack of source fit. They may already have blog posts, webinars, landing pages, and sales decks. What they often do not have is a page that cleanly answers the exact operational question a buyer typed into ChatGPT, Perplexity, Gemini, Google AI Overviews, or a search-led workflow that later spills into Reddit, YouTube, or Facebook discussion.

    Create a page for one claim, not every claim

    The mistake we see most often is trying to solve every prompt with one “ultimate guide.” That approach looks comprehensive but often creates a blurred page: too many concepts, too few clear answers, and no obvious passage for an AI system to cite.

    Instead, give every citation-targeted page one job. State the question in natural language. Answer it immediately. Explain the mechanism. Add dated facts, named systems, product constraints, definitions, and primary evidence where available. Make the limits explicit rather than hiding them. A precise limitation often makes a source more trustworthy than a page that claims universal fit.

    For example, a useful B2B SaaS page does not merely say that its product supports a workflow. It explains what happens at the handoff, what data is required, what the buyer can expect the system to do, and where human judgment remains necessary. That is the material a model can cite when a buyer asks a detailed operational question.

    This is also why focused comparisons work better than vague category pages. A buyer asking whether one approach fits a specific team, budget logic, or process constraint is creating a narrow retrieval problem. A narrow page with one clear claim has a much better chance of being selected than a broad overview trying to win every query at once.

    Make the page retrievable before making it clever

    A strong answer cannot be cited if a crawler cannot access it. Pages blocked by robots rules, login requirements, paywalls, unstable scripts, or slow rendering can be excluded before their content is even evaluated. Technical accessibility is therefore part of distribution.

    We would check that the page is publicly available, crawlable, stable, and readable without account friction. We would also use a conventional content structure: descriptive title, direct heading hierarchy, short explanatory paragraphs, labeled lists where appropriate, and schema that clearly describes the page as an article or question-and-answer resource.

    Schema is not a magic citation switch. Its value is operational: it reduces ambiguity about what the page contains. The bigger gain still comes from a page whose content is structurally clear enough to be segmented into claim-level passages without losing meaning.

    That sequencing matters. Teams often spend time polishing language and design before they verify the page can actually be discovered, rendered, and parsed cleanly. In an AI citation programme, eligibility comes first, then clarity, then polish.

    Give the model evidence it can trust

    AI systems are cautious around unsupported claims. A page full of adjectives is difficult to cite because it offers little that can be checked. A page with clear definitions, visible update dates, concrete examples, documentation links, product terminology, and qualified statements is more useful.

    This is where authority becomes an asset rather than a brand slogan. Your company needs a stable body of source material that consistently explains the same product reality across documentation, educational guides, community contributions, and relevant public conversations. Contradictory pages make it harder for machines and buyers to know what to believe.

    Useful participation on Reddit, YouTube, Facebook, and specialist communities can strengthen distribution when it adds substantive explanations rather than promotional fragments. Community sources are often selected for practical questions because they contain implementation detail, objections, and real-world context. Use those channels to clarify the same claims you want your owned pages to establish — not to spray links into conversations.

    This does not mean copying the same paragraph everywhere. It means making your explanation consistent across formats. If your help article says one thing, your comparison page implies another, and a community answer introduces a third version, you are training confusion into the public record.

    The five moves we would make this month

    If we had to turn this into an operating plan for the next few weeks, we would keep it narrow and concrete. These are this-month tasks, not abstract principles, and none of them guarantees an outcome on its own.

    • Audit technical eligibility. Review the pages you want cited and remove avoidable crawl blocks, access friction, and rendering issues that stop them being used as public sources. If an AI crawler cannot retrieve the page, excellent writing is irrelevant.
    • Track decision-stage prompts. Build a working list of the non-branded questions buyers ask in ChatGPT, Perplexity, Gemini, and search-led AI experiences this month. Flag missing brand mentions, incorrect descriptions, and competitor-led answers so the team has an actual backlog to work from.
    • Publish focused answer pages. Choose recurring customer questions from that prompt list and publish pages built around a single answer, with the answer near the top and evidence beneath it. Keep each page narrow enough to be cited for a defined claim rather than a broad category.
    • Upgrade existing pages with proof. Take the pages that already rank, earn visits, or get shared internally and replace vague positioning with definitions, constraints, dated updates, named product concepts, and links to primary material. Make every important statement easier to verify.
    • Publish one mechanics-led authority guide. Create one deep resource this month explaining how your product solves a high-value problem: how it works, what inputs it needs, what constraints apply, and where it is the wrong fit. That piece should function as a durable source asset, not another campaign post.

    The order matters. Eligibility comes before publishing, prompt tracking determines what to publish, and evidence upgrades make existing assets more useful faster than starting from zero. The authority guide then gives the site one substantial reference point that other narrower pages can support.

    Where citation programmes usually fail

    The team tracks brand mentions but not the prompts that create them

    A mention report tells you whether a model said your name. It does not tell you why you were absent, which competing source filled the gap, or which page could change the answer. Prompt-level tracking is more demanding, but it creates an actionable content backlog rather than an awareness dashboard.

    The company publishes broad thought leadership instead of answer assets

    Thought leadership can build reputation, but it is not automatically citation-ready. If the page does not resolve a particular question with specific evidence, it may be admired by humans and ignored by retrieval systems. Keep the essay, but pair it with focused pages that own the underlying questions.

    The reporting team treats visibility as conversion

    AI citations matter because they place your knowledge and brand inside a buyer’s research flow. They do not prove that the user visited, signed up, or bought. Maintain separate reporting for citations, AI-referred visits, branded demand, and commercial outcomes. That separation protects the team from claiming a direct response result that the measurement cannot support.

    The source page changes so often that the claim becomes unstable

    Freshness helps on changing topics, but constant rewrites can create a mismatch between what an AI system retrieved and what the page currently says. Update material when facts change. Preserve stable definitions and durable explanations. A source asset should become more reliable over time, not endlessly reinvent itself to chase novelty.

    There is a related failure mode here: teams optimise the homepage because it is politically visible, while the real citation opportunity sits deeper in the site. If the buyer question is specific, the winning asset is usually a specific page too.

    The advanced move: build an answer library, not a content library

    The stronger long-term strategy is an answer library linked to your revenue model. Each page should represent a question buyers ask, a claim your company can own, and evidence that supports it. Over time, these pages form a discovery layer around the business: useful in Google, retrievable by Perplexity, usable by ChatGPT, and valuable to buyers who arrive directly.

    This is also why single-channel growth is fragile. A company that depends on a homepage, a paid campaign, or a single search query has limited surface area for discovery. A company with a structured library of credible answers can appear across AI interfaces, search results, community discussions, sales enablement, and partner conversations.

    The best result is not a temporary citation spike. It is a growing body of owned, accurate, source-ready knowledge that makes your company easier to find and harder to misrepresent.

    That library mindset also keeps the work honest. Instead of asking, “What should we publish for AI?” the better question is, “Which buyer questions still lack a page we would trust as a source?” That shift turns AI visibility from a trend response into an editorial operating system.

    The operating call

    • Measure AI citations as visible page references inside AI answers, not as visits or traffic.
    • Keep AI citations and Google clicks separate, even when they are reported for the same period.
    • Use prompt tracking to identify where your brand is missing or inaccurately described.
    • Build narrow, evidence-led pages that answer one specific buyer question.
    • Protect technical accessibility, structural clarity, and factual accuracy so AI systems can retrieve and trust the page.
    • Treat every citation-targeted page as a durable distribution asset that compounds visibility and authority.

    If you remember only one thing, remember the unit: a citation is an AI answer that names or links a specific page, and it is not a visit. FinalBoss recorded 586,940 AI citations over 18 months, and in June 2026 it saw 112,585 AI citations next to 3,874 Google clicks; citations and clicks are separate units. The practical play is simple: track the prompts that matter, publish source-ready pages for those questions, and measure visibility and navigation separately.

  • How to Diagnose a Year-Long Mobile Game Plateau

    How to Diagnose a Year-Long Mobile Game Plateau

    Flat traffic for a full year is rarely an instruction to buy harder. In mobile game marketing, it is usually evidence that the game has reached a constraint the team has not named yet: weak onboarding, a broken release pattern, acquisition that overpromises, or a live game that cannot hold attention long enough to justify more spend.

    The expensive response is to start with more campaigns, new creatives, wider targeting, or a hurried app store optimization pass that does not change the product reality. That approach produces activity, not discovery. The better move is to diagnose the plateau in order: read retention cohorts, cluster App Store and Google Play reviews, trace churn to specific releases, reduce channel dependency, and replace installs or click volume as the headline metric with retained players and durable game health.

    Across the games we study, the plateau is usually architectural rather than effort-related. The team is still shipping events, buying users, refreshing store assets, and pushing updates. The problem is that the acquisition promise, first-time user experience, gameplay loop, live-ops cadence, or measurement system can no longer produce a better outcome.

    The diagnosis order matters

    These causes often coexist, but they should not be treated as interchangeable. A game with weak Day 1 retention does not need broader scaling before it fixes onboarding. A game hit by release-specific churn needs version tracing before it assumes its audience is exhausted. A game attracting the wrong players should not celebrate flat installs if those players disappear before Day 7.

    • The retention ceiling: D1, D7, and D30 cohorts show where players stop coming back.
    • Promise mismatch: the traffic may install, but it may not match the game the player actually finds.
    • Release dilution: specific versions, events, or economy changes may be poisoning retention and ratings.
    • Channel dependency: one acquisition surface may be doing too much of the work.
    • Wrong measurement: install volume can conceal churn, weak cohorts, and wasted spend.

    This is not just an ASO cleanup exercise. It is a product-marketing and live-ops decision. Store visibility matters, but app store traffic alone cannot carry a game whose early cohorts tell you players are not finding a reason to return.

    Key takeaways: Use classic retention unless you clearly label otherwise; classic retention counts only players active on exactly that day, while rolling retention counts anyone active on that day or later and therefore reads higher. The basic formula is simple: retention rate on Day N equals players from that install cohort who opened on Day N divided by the total players in that cohort, multiplied by 100. In practice, D1 is your onboarding ceiling, D7 tests habit formation, and D30 tests depth, loyalty, and whether the economy can support long-term play.

    Reason one: You have reached the retention ceiling, not necessarily the traffic ceiling

    A year-long plateau in mobile game marketing is often misread as an acquisition problem when it is really a retention problem. If D1 is weak, more traffic simply gives you more people to lose. If D7 collapses after a decent first day, the game is buying attention it cannot convert into habit. If D30 never stabilizes, the title may have enough early curiosity but not enough depth to become a durable business.

    Check retention before touching scale. Spend can improve access to demand that exists. It cannot manufacture attachment that the game does not create.

    We would begin by mapping classic D1, D7, and D30 by install cohort, platform, source, country, and release version. That matters because a flat blended average can hide a very different truth: one cohort may be healthy, another may be broken, and a third may be carrying the graph only because paid spend kept flowing.

    The order inside retention matters too. Fix onboarding and the first-time user experience, or FTUE, before optimizing late-game retention. D1 is the ceiling for later cohorts. If players do not understand the promise, the controls, the reward structure, or the reason to return in the first session, no amount of mid-game tuning will rescue the users who never stayed long enough to see it.

    Published mobile benchmark ranges vary by methodology, so a single universal target is the wrong way to think about retention. What matters is whether your title is moving toward a strong pattern or away from one. Monopoly GO is a useful contrast case here: about 50% D1 retention on both platforms, 21 to 24% D7, and 12 to 15% D30. Most games will not reproduce that profile, but it shows what happens when acquisition quality, onboarding, and repeat reasons to return reinforce each other instead of fighting each other.

    A diverse team collaborating on digital marketing strategies at a desk, using laptops and tablets.
    A diverse team collaborating on digital marketing strategies at a desk, using laptops and tablets.

    If your game cannot approach a healthy D1, D7, D30 shape over time, the problem is usually upstream in acquisition quality or inside the opening experience itself. That is the first ceiling to name, because every later decision sits under it.

    Reason two: Your traffic is not your players

    Intent mismatch exists in mobile games too. The ad can be compelling, the store page can convert, and the install graph can look acceptable, while the audience arriving is still wrong for the actual game. In that case, the plateau feels confusing because top-of-funnel activity remains visible, but the player base never compounds.

    The familiar pattern is an acquisition promise built around one fantasy while the game delivers another. A puzzle ad brings in users who wanted a clean puzzle experience but the product quickly reveals a heavier economy or broader progression layer. A competitive promise attracts users looking for fair matchmaking, but the first sessions feel noisy, unstable, or punishing. The campaign wins the click. The game loses the player.

    We would audit traffic by retained behavior, not by install count alone. Compare the themes in creatives and store positioning with the complaints and praise showing up after install. If App Store and Google Play reviews repeatedly center on crashes, broken progression, balance backlash, or monetization friction, the issue is not simply that the campaign underperformed. The issue is that the market was invited into an experience that did not match the promise.

    This is where the gameplay loop matters. The gameplay loop is the repeated cycle of player action, game response, reward, and motivation to do it again. Core loops happen in seconds, session loops over minutes, and meta loops over days or weeks. If your store page sells one loop but the product reveals another, retention drops even when traffic appears healthy.

    Competitor reading helps here, but only if it is done with discipline. Review monitoring on category leaders can show what players value in the genre: generous rewards, fair matchmaking, event variety, and stable performance are recurring hooks. That is useful whether you are studying a long-running game like Brawl Stars, Clash Royale, Genshin Impact, or Candy Crush Saga. The point is not to copy their surface features. The point is to understand what players are rewarding with attention and what they punish with churn.

    The mistake we see most often: treating every install as equally valuable. A game does not need more traffic in the abstract. It needs more of the right players entering a version of the game that earns a second session.

    Reason three: Releases that never recovered are diluting everything else

    A mature live game can become an archive of past assumptions just as easily as a mature content site can. Old features, rushed events, economy tweaks, tutorial changes, and unstable builds can keep affecting ratings and retention long after the team has moved on to the next update. Keeping scale constant through that damage feels efficient. In practice, it can make the plateau last longer.

    The fastest way to see it is to trace churn against releases. Line up D1, D7, and D30 cohorts by install date and version, then compare the breaks with app store review clusters. The first 24 to 72 hours after every release are the highest-risk window because players report crashes, broken progression, and balance backlash in stores before analytics fully confirm the pattern. If you wait for the month-end dashboard, you are already late.

    A review workspace such as AppFollow can help here because it lets teams collect App Store and Google Play reviews in one place, then tag them by topic and sentiment. Bug, balance, monetization, fraud, praise, and feature request are the obvious clusters. The useful move is not just collection. It is routing reviews by app, language, severity, version, and repeated phrases so product, live ops, support, and marketing are looking at the same failure pattern.

    That gives you a readable decision layer instead of a pile of anecdotes.

    Decision When it is justified What it protects
    Pause or reduce scale D1 or store rating breaks after a specific release, and review clusters center on crashes, blocked progression, or severe instability. Paid budget, cohort quality, and the next reporting cycle from being distorted by a broken build.
    Retune onboarding and FTUE Install volume holds, but D1 is weak across sources and reviews point to confusion, early friction, or an unclear first reward. The ceiling for D7 and D30, because later retention cannot outperform a failed first session.
    Add mid-game depth D1 is acceptable, but D7 drops sharply and players describe repetition, weak event variety, or too little reason to return. Habit formation, session frequency, and the transition from novelty to routine play.
    Rework economy, fairness, or monetization pressure D7 or D30 worsens after an economy or balance change, and review clusters center on paywalls, unfairness, or backlash. Long-term trust, payer conversion quality, and late-game retention.

    Pruning in games is not about deleting features impulsively, just as pruning in publishing is not about deleting pages impulsively. Some systems are slow-burn. Some events support retention indirectly. Some features matter because they answer a player need before that player is ready to spend. The test is strategic contribution, not whether the team is emotionally attached to the release.

    When a specific build or event created the damage, name it. A year-long plateau often turns out to be several short retention shocks that were never connected back to the release history.

    Reason four: One channel only is a ceiling by design

    One channel only is a ceiling by design in mobile game marketing too. If the game depends on one paid source, one store surface, one featuring pattern, or one burst strategy, the business is limited by that channel’s costs, policies, audience shape, and timing. That is not resilience. It is dependency disguised as momentum.

    Store traffic should remain important because it captures existing demand and category browsing intent. Paid user acquisition should remain important because it can create controlled testing conditions. But a game cannot build its future solely around one source of installs while ignoring community, creator discovery, cross-promotion, owned CRM, or the role that strong review health plays in conversion and trust.

    The largest mobile games do not behave as if one route to discovery is enough. Brawl Stars, Clash Royale, Genshin Impact, and Candy Crush Saga are useful reminders not because they offer a single tactic to copy, but because enduring live-service games benefit from multiple reinforcing systems: brand memory, social circulation, updates, community habits, and repeat reasons to return.

    We would add one repeatable acquisition or reactivation motion before chasing broad diversification. The right choice depends on the game: creator partnerships, community loops, push reactivation, cross-promo, or a cleaner paid testing structure. The objective is not to be everywhere. It is to ensure that a shift in one surface cannot stall the entire player pipeline.

    This is also where pacing discipline matters. Automated pacing rules can pause campaigns that reached their monthly limit to prevent bleeding into the next cycle’s numbers. More importantly, a title coming off a harmful release should not keep receiving full-scale spend just because the calendar says the budget is available. A channel can hide a product problem for a while. It cannot solve it.

    Reason five: You are measuring installs instead of the game

    Total traffic and total installs are incomplete metrics because they treat a retained player, a churned player, a frustrated reviewer, and a player who never finished the tutorial as equivalent. They are not equivalent to the business.

    A plateau can hide a deeper problem: acquisition remains flat or grows slightly while cohort quality declines. That happens when teams keep adding creative, increasing spend, or celebrating store conversion without checking whether the players acquired in that window survive past the first few sessions. It also happens when classic retention and rolling retention are mixed together in reporting, making the game look healthier than it is.

    We would replace the install-only review with a game-health review that connects marketing, product, and live ops to meaningful outcomes.

    • Track classic D1, D7, and D30 by install cohort, source, platform, and release version.
    • Separate onboarding failures from mid-game depth problems and late-game economy problems.
    • Review App Store and Google Play feedback by topic, star pattern, language, and repeated phrases.
    • Watch the first 24 to 72 hours after every release as a dedicated risk window, not as routine noise.
    • Judge campaigns by the quality of retained cohorts, not only by the volume of cheap installs.

    This does not mean every campaign needs to produce immediate long-term loyalty on its own. It means every campaign and every release need a defined role. Some acquire efficiently. Some reactivate effectively. Some support monetization. Some protect reputation. Channels and updates without a role are usually the ones that accumulate until the plateau becomes a habit.

    What we would do now

    Start with classic D1, D7, and D30 by cohort and version. Then cluster App Store and Google Play reviews, trace the breaks to specific releases, and decide whether the root cause is onboarding, content depth, balance, or monetization pressure. After that, reduce single-channel dependence and scale only the cohorts the game can actually retain.

    The objective is not simply to restart an install graph. It is to build a marketing system that respects product reality, catches churn in the first few days after every release, and turns traffic into players who stay. Done right, the team ends with clearer signals, faster prioritization, healthier reviews, and growth that compounds instead of resetting every month.

  • How We Would Fix Google Showing the Wrong Company for Your Brand

    A buyer enters your exact company name into Google and lands on an unrelated business in another country. That is not a minor SEO issue. It is a distribution failure at the highest-intent moment in your buyer journey.

    The usual reaction is to look for a setting in Google Search Console, file feedback, or publish more content. We would not start there. Search Console verification gives you access to site data; it does not tell Google which organisation your brand name represents.

    When Google shows the wrong company for a branded search, it has resolved the name to the wrong entity: a different organisation profile with a stronger or more coherent combination of category, geography, website signals, links, directory data, and third-party references. The fix is entity reconciliation: making every meaningful signal say the same thing about your company until Google, Bing, AI Overviews, and AI assistants have less reason to confuse you with someone else.

    What we would fix first: the entity, not the ranking

    A same-name competitor can outrank you even when your own website is technically sound. The other company may simply have a longer-established domain, a clearer category, better directory coverage, stronger inbound links, or a more complete presence in organisational data sources.

    This distinction matters. Trying to “rank for your name” with generic blog posts treats the symptom. The strategic job is to establish an unambiguous answer to four questions everywhere your company is represented:

    • What is the exact company name?
    • What category does the company operate in?
    • Who does it serve?
    • Which market or region does it operate in?

    For a B2B company with a name collision, the category and market qualifiers are often the decisive differentiators. “Brand name” alone may remain ambiguous in some regions. “Brand name + staffing” and “brand name + EU institutions” can become clear much faster because they tie your name to the commercial reality that belongs only to you.

    Our recommendation: treat this as a six-part entity system, completed in order. Do not spend heavily on paid brand campaigns or broad content production before the system is coherent. Paid visibility can mask a weak brand entity; it does not repair one.

    The case: zero owned results became four in the top four

    We applied this approach to a staffing company serving EU institutions across EU member states. Its name was identical to an unrelated company in another country, operating in a different industry.

    Before the work, an exact search for the staffing company’s name on EU Google returned zero pages owned by the company on the first page. The dominant result was the same-name company from another country. Adding “staffing” or “EU institutions” to the company name still produced the wrong business, mixed results, and generic job boards rather than the actual staffing company.

    The problem extended beyond traditional search. Perplexity and other AI assistants attached the company name to the unrelated business’s industry and country, using the wrong company’s website as the primary source. That is what happens when an organisation has built a website but has not yet built a durable entity footprint across the web.

    Five days after the fixes were implemented, the staffing company ranked number one on EU Google for its company name plus “staffing,” and number one for its company name plus “EU institutions.” For the exact company-name search, four results owned by the company occupied the top four positions, including its homepage, service page, company page, and LinkedIn presence.

    On 2 September 2026, Perplexity described the business correctly as a staffing company serving EU institutions, with the company’s own website listed as the first source. The important point is not that every company will see the same movement in five days. It is that entity repair can move far faster than founders assume when the underlying signals are contradictory rather than merely weak.

    1. Choose one canonical host and defend it everywhere

    The first decision is simple and non-negotiable: your company needs one primary web address. If your name appears across multiple domains, subdomains, old sites, language mirrors, or inconsistent URL formats, you are asking search engines to decide which version is authoritative.

    We would select one HTTPS host as the canonical home of the brand, redirect old domains and alternate hosts to it, and make that host the only URL used in email signatures, sales materials, LinkedIn, directories, partner profiles, and press mentions.

    The mistake we see most often: a team updates the new website but leaves an old domain in LinkedIn, a directory listing, or a recruitment profile. That creates a split identity: your site says one thing, while external sources keep validating another location.

    Keep legacy Search Console properties for historical data if needed, but use the canonical domain property for monitoring the business going forward. Search Console is an observation and indexing tool here, not the authority that chooses your brand entity.

    2. Fix sitemap and canonical signals before publishing more pages

    Once the canonical host is chosen, Google needs a clean technical map of the company. We would create a single XML sitemap containing the homepage, company or about page, key service pages, and contact page. Staging pages, test URLs, thin campaign pages, and obsolete duplicates do not belong in that sitemap.

    Submit that sitemap through Search Console and monitor whether it processes successfully. Then audit canonical tags so duplicate URLs, tracking-parameter URLs, old paths, and alternate versions point toward the intended primary version.

    For companies serving multiple EU markets, multilingual pages require particular discipline. Each language version can serve its audience, but the core company description must remain conceptually identical. Use hreflang where relevant, maintain one primary version for each language region, and avoid letting translated pages describe the company as different categories in different markets.

    This is not glamorous work, but it prevents authority from being scattered across pages that all compete to explain who you are.

    3. Make the website describe the company without ambiguity

    Your homepage is not only a conversion asset. It is the primary source from which search engines and AI systems infer the organisation behind the name. A homepage that leads with abstract positioning, slogans, or vague promises can be polished and still fail at entity resolution.

    We would make the first screen and the company page explicit. The exact company name, company type, market served, and regional scope should appear in normal language. For the staffing-company case, the essential statement was clear: the business is a staffing company providing staff to EU institutions.

    That language belongs in the page title, H1, opening copy, service-page headings, and the company or about page. The goal is not keyword repetition. The goal is a consistent name-to-category-to-market association that a buyer, a crawler, and an AI assistant can all interpret correctly.

    We would also implement Organisation and Website structured data using the exact company name, canonical URL, and official social profiles in the sameAs field. Service markup can reinforce the commercial category when it accurately reflects the business. Do not add categories that overlap with the unrelated company simply because they sound broader or more searchable. Broad positioning often creates the ambiguity you are trying to remove.

    4. Repair LinkedIn before chasing low-value social activity

    For B2B companies, LinkedIn is not just a social channel. It is a high-value organisational reference point. A thin company page with the wrong industry, a vague description, or an outdated website link gives Google and AI systems weak evidence at exactly the point they need clarity.

    We would align the LinkedIn Company Page with the website:

    • Use the exact legal brand name.
    • Select the closest accurate staffing or recruiting industry category.
    • Use a concise tagline that states the category and market served.
    • Write an About section that repeats the core company description in natural language.
    • Link only to the canonical website host.
    • Publish a company post that connects the brand name with staffing for EU institutions.

    The point is consistency, not social reach. A company page that describes you precisely is more valuable to entity reconciliation than a stream of generic posts with no category signal.

    5. Standardise directory listings with one approved company sentence

    Google’s Knowledge Graph maps relationships between organisations, websites, categories, and third-party references. That means your company is evaluated partly through what the wider web says about it, not just what you publish on your own domain.

    We would create one approved entity description and use it consistently across relevant business databases, staffing and HR directories, professional networks, review platforms, and organisation profiles. For this case, the sentence was structurally simple: the company is a staffing company providing staff to EU institutions.

    Audit each listing for the same five fields: exact name, category, description, region, and canonical URL. Remove any old description that places the company in the same category as the unrelated business. If a profile cannot be corrected, document it and prioritise stronger, more authoritative listings rather than compensating with low-quality directory submissions.

    Low-quality directories do not create authority. They create more versions of the story. Authority comes from credible sources repeating the correct one.

    6. Earn independent mentions that confirm the category

    Your own site can declare what you are. Independent sites help validate it. This is where distribution becomes an asset rather than a marketing afterthought.

    We would secure at least two earned mentions from authoritative sites relevant to the company’s market: EU-focused staffing associations, trade publications, institutional-services vendor directories, or credible partner pages. Each mention should use the exact brand name, describe the company as a staffing company serving EU institutions, and link to the canonical host.

    Do not pursue mentions merely because a site has high authority. A prestigious but contextless link is weaker for this specific problem than a relevant mention that clearly connects your name to the right category and audience. The useful signal is not just “this domain linked to us.” It is “this independent source confirms what this company is.”

    How we would measure whether the entity is actually repaired

    Do not declare success because one personalised search looks better. Use a compact recurring scorecard across search and AI systems.

    • Search the exact company name on EU Google and record how many owned properties appear prominently.
    • Search the company name plus the defining category and market qualifier.
    • Check the company name in Google AI Overviews when available.
    • Run the same branded checks in ChatGPT, Gemini, Perplexity, and Claude.
    • Record every URL used in AI answers, the description given, the companies confused with yours, and the date.
    • Monitor Search Console for branded-query impressions and clicks after the technical changes.

    For earned-mention monitoring, set Google Alerts to at most once a day for a single digest, then add a weekly manual search pass. Alerts miss community forums, niche publications, and subreddits. In Semrush, filter backlinks by Anchor and enter the brand name to identify links where the company name is used as anchor text.

    We would report this to leadership as an entity-visibility system: correct brand description, owned-result coverage, authoritative third-party confirmations, and AI-answer accuracy. That is more useful than a raw ranking report because it shows whether the market can identify the business correctly.

    Where this work usually fails

    • Submitting feedback before repairing primary sources: knowledge-panel feedback is more credible once your website, LinkedIn page, and directories provide consistent evidence.
    • Expecting Search Console verification to solve the issue: it will not change entity selection on its own.
    • Changing only the homepage: a clear homepage cannot overcome conflicting external listings and old domains.
    • Using broad, vague positioning: category ambiguity gives the same-name company more room to own the query.
    • Buying generic links: entity reconciliation needs relevant context, not a larger but noisier backlink count.
    • Ignoring AI results: wrong answers in Perplexity, ChatGPT, or AI Overviews reveal that the web’s entity signals are still unresolved.

    The strategic lesson: discovery is a business function

    A company cannot build authority if buyers cannot find the correct company when they already know its name. This is why visibility compounds only when it is structured: one canonical destination, one coherent entity description, one consistent set of profiles, and independent references that reinforce the same commercial truth.

    The staffing-company result did not come from publishing more content or finding a hidden Google setting. It came from turning fragmented signals into one legible organisation across the web. That is the work founders should fund early: not content for content’s sake, but a discovery system that makes the company recognisable wherever buyers, search engines, and AI assistants look.

    The key moves

    • Choose one canonical host and redirect every alternative to it.
    • Clean up sitemap, canonical tags, and multilingual page relationships.
    • State the exact name, category, market, and region clearly on the website.
    • Align LinkedIn and credible directory listings around one approved company description.
    • Earn third-party mentions that connect the brand name to the right category.
    • Track branded results and AI answers until the correct entity becomes the consistent answer.
  • How We Would Build New Website Traffic: Our 24-Week Curve

    How We Would Build New Website Traffic: Our 24-Week Curve

    A new website does not need more “content” in the abstract. It needs to become discoverable for useful, specific demand — and it needs a system that keeps earning that discovery after launch.

    That distinction matters more in 2026. AI Overviews can satisfy broad informational searches without sending a visit. Social distribution is inconsistent. A founder can publish a thoughtful article, share it once, and conclude that the market does not care. Usually, the problem is not demand. The problem is that the business has not yet built enough entry points for demand to find it.

    We saw the opposite play out on an unnamed travel property launched on a domain registered early in 2026. No paid ads were used. The work was deliberately unglamorous: establish technical discovery, publish the first 20 pages around real planning questions, maintain a weekly cadence, then widen discovery through Bing and AI-answer visibility.

    The result was not an overnight spike. It was a compounding curve. Google weekly clicks moved from 0 in the week of 2 March 2026 to 140 in the week of 4 May, 907 in the week of 29 June, and 1,587 in the week of 17 August. Weekly Google impressions moved from 42 to 61,881 across that period.

    The curve: what happened across the launch

    The important lesson is not that every new site will reproduce these numbers. It is that early traffic follows a different operating logic from mature-site traffic. At the start, the job is not “rank for the category.” The job is to create enough useful, indexable surfaces that search engines can understand the site, test it against relevant searches, and find evidence that the pages deserve continued exposure.

    Week beginning Google weekly clicks Google weekly impressions
    2 March 2026 0 42
    4 May 2026 140 —
    29 June 2026 907 —
    17 August 2026 1,587 61,881

    That is the pattern founders should plan for: low initial visibility, then a period where impressions expand faster than clicks, followed by a stronger click curve once the site has accumulated more relevant pages and more search-query evidence. Visibility compounds when useful pages reinforce one another. A single excellent homepage does not.

    Our recommendation: build a discovery system before chasing traffic

    The mistake we see most often is treating launch as a publishing event. The site goes live, a few broad articles appear, and the team waits for traffic. That approach leaves too much to chance because it confuses content production with distribution.

    We would approach a new site as a discovery system with four connected jobs:

    • Make the site crawlable and legible. Search engines need a clear path to find priority pages.
    • Publish for real demand, not internal messaging. Early pages should resolve the questions a buyer or planner already has.
    • Maintain a weekly publishing and improvement rhythm. Consistency creates more opportunities for discovery and gives the site a coherent topical shape.
    • Spread risk across discovery surfaces. Google matters, but single-channel growth is fragile. Bing, LinkedIn, AI-answer visibility, and owned follow-up paths all reduce dependence on one gatekeeper.

    This is not a call to publish endlessly. It is a call to make every page earn its place in the system. The first useful pages create discovery. Later pages improve coverage, internal relevance, authority, and commercial intent.

    Phase one: remove the technical reasons a useful page stays invisible

    Before writing more, make sure Google can find the pages that already exist. Google Search Console remains the primary first-party operating layer for this work. Submit the XML sitemap, inspect priority URLs, and use URL Inspection → Request Indexing for pages that materially matter to the business.

    The judgment call here is simple: request crawling for the pages that can become meaningful entry points, not every minor update. A crawl request is not a ranking strategy and it is not a guarantee of indexing. It is a direct signal that a page exists and merits another look.

    Team working on marketing strategy using data charts and papers in an office meeting.
    Team working on marketing strategy using data charts and papers in an office meeting.

    At this stage, diagnose the basic blockers with discipline:

    • A page marked noindex cannot become a search entry point.
    • A conflicting canonical can tell search engines that another version is the page that matters.
    • Thin pages give search engines little reason to retain or surface them.
    • Orphaned pages are difficult to discover because nothing important on the site points to them.

    Founders often delegate this setup and never revisit it. That is expensive. Discovery is a business function. If a category page, product page, or decision-making guide cannot be crawled and indexed properly, the company has built an asset that its market cannot find.

    Phase two: use the first 20 pages to answer demand already in motion

    The first 20 pages on the travel property were not a random editorial calendar. They were built around real questions a person faces while planning and deciding. That is the correct early-site standard in any B2B category: publish pages that reduce uncertainty at the moment somebody is trying to make progress.

    For a founder-led business, this usually means resisting broad thought leadership at the beginning. “The future of the industry” may be interesting, but it is rarely the best first discovery asset. A page that clarifies a concrete choice, explains a constraint, compares approaches, or helps someone prepare for the next decision has a clearer reason to exist.

    We would structure the early library around connected intent rather than isolated keyword targets:

    • Decision pages: pages that help a visitor evaluate an approach, service, destination, or next move.
    • Planning pages: pages that reduce practical uncertainty before someone commits.
    • Comparison pages: pages that distinguish meaningful alternatives without manufacturing false differences.
    • Proof pages: pages that show how the business thinks, works, or produces an outcome.

    The pages should link to one another where the next question naturally follows. This is not an internal-linking exercise for its own sake. It is how a site turns individual answers into a useful body of knowledge. Search engines see clearer relationships; visitors find the next relevant page; the business starts to accumulate authority around a defined problem.

    Do not publish pages that merely restate an answer AI can summarize in a sentence. Add judgment, usable detail, a decision framework, original framing, or a functional next step. In a travel context, a generic explanation is easy to compress. A page that helps someone make a practical choice has a stronger reason to earn attention.

    Phase three: protect the weekly cadence from founder distraction

    A weekly cadence matters because authority is an asset built through accumulation. Each strong page becomes another route into the business, another internal link destination, another piece of evidence about what the site is for, and another source for future distribution.

    Two adults in an office discussing marketing strategy around a round table.
    Two adults in an office discussing marketing strategy around a round table.

    The wrong operating model is to publish in bursts when the team has spare time. That creates a library with gaps, little feedback, and no compounding process. The better model is to keep a simple loop: publish a useful page, confirm it can be discovered, watch the queries and impressions it earns in Google Search Console, improve the page when the data reveals a mismatch, and use the resulting insight to choose the next page.

    Search Console is especially valuable here because it shows the difference between a page that has no discovery and a page that is gaining impressions but failing to earn clicks. Those are different problems. No impressions often points to discovery, relevance, or competition. Growing impressions with weak clicks often points to a title, positioning, or intent mismatch.

    That is why systems outperform manual effort. A founder should not be reviewing every page from scratch. The team needs a repeatable decision rhythm that turns search data into the next publishing and improvement priorities.

    Phase four: broaden discovery beyond Google without faking attribution

    Google was the measured traffic engine in this curve, but relying on Google alone would be the wrong strategic conclusion. A new business should build multiple ways to be found.

    For Bing, establish the site in Bing Webmaster Tools, use the Google Search Console import path where available, submit the sitemap, and connect IndexNow through the implementation supported by the site’s CMS or infrastructure. The operating goal is straightforward: newly published or materially improved pages should have a clear path into another major discovery system.

    LinkedIn belongs in the system as a distribution layer, not as a place to repost links mechanically. Turn the commercial insight behind a useful page into a sharp operator-level observation. The post earns attention in the feed; the site holds the deeper explanation; the business compounds authority in both places.

    AI-answer visibility should be treated with the same discipline. It is an emerging discovery surface, not a metric to inflate. An appearance in an AI answer is not a Google click and should not be counted as traffic. The useful strategic response is to publish clear, structured, genuinely helpful material that makes the business understandable wherever people now ask questions.

    A vibrant diagram showcasing a marketing strategy wheel with various industry sectors and user categories.
    A vibrant diagram showcasing a marketing strategy wheel with various industry sectors and user categories.

    What to expect at week 4, week 12, and week 24

    Week 4 is the validation stage. The priority is not a traffic target. It is evidence that the site can be crawled, indexed, and associated with relevant searches. Founders who panic here often abandon the strategy before the search system has enough material to evaluate.

    Week 12 is the pattern-recognition stage. The site should have enough connected material to reveal which questions generate impressions, which pages attract the wrong audience, and where the next high-value pages belong. This is where generic publishing should give way to sharper editorial decisions.

    Week 24 is the compounding stage. The objective is a library that no longer depends on one launch post, one social push, or one homepage visit. The travel property’s movement from no weekly Google clicks to 1,587 weekly Google clicks illustrates what becomes possible when discovery, content quality, and consistency work together over time.

    The advanced move: build function where information is becoming cheap

    As AI makes basic explanations easier to obtain, purely informational pages become less defensible. The strongest expansion move is often a free, single-purpose tool that helps a visitor do something: turn inputs into a useful output, simplify a planning task, or reduce a repetitive decision.

    This should not be a gimmick built because “tools get links.” Build it only after the site’s search data and customer conversations reveal a recurring task that the business can genuinely simplify. A useful tool creates a different kind of value from an article. It is harder to summarize, more likely to be reused, and capable of becoming a durable discovery asset.

    The broader point is that distribution beats content when content is treated as an inventory item. Content wins when it is part of a system: discoverable pages, functional utility, repeatable publishing, strong positioning, and multiple paths back to the business.

    The operating call

    • Set up Google Search Console so priority pages can be found, inspected, and submitted for crawling.
    • Build the first 20 pages around real decisions and practical questions, not broad internal messaging.
    • Maintain a weekly cadence that uses search evidence to improve the next publishing decision.
    • Add Bing, LinkedIn, and AI-answer visibility as complementary discovery layers rather than substitutes for organic search.
    • Measure Google clicks and impressions honestly. Do not turn visibility signals into fictional traffic.
    • Graduate from information to functional utility when repeated demand reveals a problem worth solving.

    The lesson from the 24-week curve is not that new-site growth is easy. It is that it is operational. Companies that treat discovery as a recurring business function build visibility that compounds. Companies that treat it as a launch task keep rebuilding attention from zero.

  • The First-Hour Checklist for an Invisible Launch

    The First-Hour Checklist for an Invisible Launch

    A polished site can be live, fast, and full of thoughtful copy while being effectively absent from the market. The failure is rarely that nobody wants what the company sells. More often, the launch has broken the route between the business, search engines, and the channels that should send people in.

    “You launched and nobody came” is usually a discovery problem before it is a demand problem. The first response should not be redesigning the homepage, publishing more articles, or debating campaign creative. It is proving that the real domain is reachable, crawlable, indexable, measurable, and connected to a real distribution path.

    Across B2B launches, the mistake we see most often is checking analytics before checking whether Google has been told where the company actually lives. Analytics can confirm a visit. They cannot repair a blocked crawler, a broken redirect, or a canonical tag pointing to a preview environment.

    TL;DR

    • Start by checking whether every version of the domain resolves to one real production home.
    • Then check whether crawlers are allowed in: robots.txt, meta robots, and server-level indexing directives.
    • Confirm that the sitemap and canonical tags name the production domain, not a preview or legacy host.
    • Use Google Search Console to compare the canonical you declare with the canonical Google selects.
    • If searching your brand returns zero owned pages, treat that as a launch fault, not a patience problem.
    • Only after those checks should you worry about analytics, campaigns, or more content.

    The diagnosis: a live website can still be pointing search elsewhere

    A staffing company serving EU institutions made this failure painfully clear. Its public site had launched, yet searching the company’s name returned zero pages it owned. The issue was not brand awareness alone. Its XML sitemap and page-level canonical tags pointed to a preview hosting domain instead of the real production domain. At the same time, the bare production domain returned 404 pages.

    Google was being told that the real company lived somewhere else. The browser-facing site looked present, but the signals that matter for discovery contradicted the business’s intent. A prospective buyer, candidate, or partner searching by brand name had no reliable route to the production site.

    That is why we would treat the first-hour checklist as a business-critical launch control, not an SEO tidy-up. Discovery is a business function. If a company cannot be found when someone searches directly for it, every sales asset, partnership, launch post, and piece of authority-building content is working with a broken destination.

    The important term here is canonical. A canonical tag tells a search engine which URL should represent a page. Canonicalization is the search engine’s process of deciding which version is the preferred one. If your sitemap, redirects, and canonical tags disagree, Google has to choose among conflicting signals. In the staffing-company case, those signals were not merely messy. They were actively pointing away from the business’s real home.

    What to have ready before you begin

    This is not a broad site audit. It is a focused handover check designed to establish whether the production site is capable of being discovered. Bring together the person who can change domain and deployment settings, the person responsible for the site’s content and marketing, and access to the systems that show search and analytics status.

    • The intended production domain and preferred public version of it.
    • A short list of revenue-critical pages: homepage, core service pages, job or product pages, and contact or conversion pages.
    • Access to the site’s domain configuration, sitemap, robots settings, and deployment environment.
    • Access to Google Search Console and the analytics property used by the production domain.
    • A named owner who can make a decision and resolve a fault immediately.

    Those inputs matter because the first hour is not for theory. It is for checking whether the same answer appears everywhere. When a browser, a crawler, and a search engine ask where the company lives, they should all arrive at the same production domain. If one person sees the right homepage while Google is being handed a preview host, the launch is not healthy.

    Do not turn this into a committee exercise. The goal is to make the production domain internally consistent. Every technical signal should reinforce the same answer when a crawler asks: “Which version of this page is real?”

    The first-hour checklist, in the order we would run it

    Start with reachability and domain consolidation

    Open the public site through every common variation of the domain: the bare version, the secured version, and any version using a www host. They should resolve to a single preferred public host through permanent redirects, rather than loading duplicate versions or failing altogether.

    What you want to see is consistency. The homepage and critical commercial pages should load from the intended production host, and alternate versions should support that choice rather than compete with it. A healthy launch gives a crawler one clear route. An unhealthy launch makes the same company appear to live in several places at once.

    The homepage and critical commercial pages must return a successful server response and display the real production content. A public-looking page that sends visitors to a placeholder, staging banner, login wall, or error page is not live in the only sense that matters.

    The staffing-company example shows why this goes first. The bare domain returned 404 pages. Even if the preferred host loaded correctly, that missing root-level route weakened the clarity of the entire launch. Domain variants are not a cosmetic detail; they are competing statements about where the business exists.

    That is also why a founder should take the symptom seriously when brand search returns zero owned pages. If one path to the site breaks at the root while another path works in a browser, the team may assume the launch is basically fine. Search engines do not grade on that curve. They read the conflicting signals as evidence that the site is not fully settled.

    Common mistake: accepting temporary redirects or allowing multiple versions of the site to load independently. That fragments signals and makes the search engine’s canonical choice less predictable. Choose the production host deliberately, then make every other route support it.

    A vibrant diagram showcasing a marketing strategy wheel with various industry sectors and user categories.
    A vibrant diagram showcasing a marketing strategy wheel with various industry sectors and user categories.

    Remove crawl and index blocks before looking at traffic

    Next, inspect robots.txt on the live domain. It should load publicly and allow crawlers to reach the sections that matter to the business. A staging-era block such as Disallow: / can survive a launch even when every page looks correct in a browser.

    Then inspect the homepage and key page templates for noindex directives. Check both page-level meta robots settings and server-delivered X-Robots-Tag headers. Teams often remove a visible staging banner and assume the environment is production-ready, while a hidden noindex instruction remains active upstream.

    For a B2B company, protect the paths that create commercial discovery: service pages, job listings where relevant, expertise pages, and the pages used in sales outreach. If those routes are blocked, the site may technically exist while the market has no dependable way to find it.

    What you should see here is absence of contradiction. The live domain should not say “index me” in one place and “keep out” in another. If the brand search symptom is zero owned pages, crawl blocks are among the first explanations to clear. Until they are ruled out, low traffic numbers do not tell you much.

    This is the point where teams often lose time because the site feels finished. The copy is approved. The design is approved. Internal stakeholders can click around and reach the pages they expect. None of that proves those pages are eligible to appear in search. The first-hour checklist is meant to separate human visibility from search visibility.

    Make the sitemap describe the production business, not the preview build

    The XML sitemap is one of the clearest machine-readable declarations of what the company wants indexed. It should be reachable on the production domain and contain only production URLs that are intended to appear in search and load successfully.

    Do not treat a sitemap as a box to tick. It is a distribution instruction. In the staffing-company case, the sitemap listed preview-hosting URLs. That sent Google toward a version of the company that the business did not intend prospects to see.

    What you want to see is that the sitemap reads like a clean inventory of the public business. The homepage URL should be on the production host. So should the major service pages, contact pages, and any other indexable assets that matter commercially. Preview URLs, redirected URLs, error pages, and blocked pages do not belong there.

    This section matters more than many teams realize because the zero-owned-pages symptom can persist even when a site looks polished. If the sitemap names the wrong host, you are effectively publishing a map to somewhere else. Submitting that sitemap quickly does not solve the problem. It simply accelerates the wrong instruction.

    Add the sitemap location to robots.txt, then submit the production sitemap through Google Search Console and Bing’s webmaster tools. Submit only after the URLs are correct. A fast submission of the wrong sitemap simply accelerates the wrong instruction.

    Check canonical tags on the pages that carry commercial intent

    A canonical tag tells search engines which URL should represent a page. On a unique, indexable production page, the canonical should point back to that same page using an absolute production-domain URL.

    A diverse team collaborating on digital marketing strategies at a desk, using laptops and tablets.
    A diverse team collaborating on digital marketing strategies at a desk, using laptops and tablets.

    Check the homepage first, then inspect the major templates: service pages, job pages, resource pages, and any landing pages tied to active sales or marketing activity. The declared canonical should not point to a preview host, a legacy domain, a generic category page, or a different page in a chain.

    What you should see is self-consistency. A unique page should name itself on the production domain. If several important pages point their canonicals elsewhere, the site is effectively arguing against its own discoverability.

    This is the highest-leverage check in a launch that looks live but cannot be found. In the staffing-company example, the canonical tags reinforced the sitemap error. Together, they gave Google repeated evidence that the preview host — not the production domain — was the authoritative home of the company.

    That is the exact sort of fault that produces the strange but revealing result founders describe as, “The site is up, but searching our name shows nothing we own.” When the declared canonical and the production domain disagree, search can follow the declaration instead of the team’s assumption.

    Do not use canonicals to compensate for messy domain management. Redirects, internal links, sitemap URLs, and canonical tags should all agree. A canonical is a strong signal, but a consistent site-wide pattern gives Google far less room to choose a different version.

    Use Search Console to confirm what Google sees

    Once the public routes, crawl rules, sitemap, and canonical tags are aligned, inspect the homepage and priority pages in Google Search Console. Confirm that the inspected URL belongs to the intended production property, then compare the user-declared canonical with the canonical Google selected.

    This is the moment where opinion gives way to diagnosis. If your declared canonical and Google’s selected canonical match on the production domain, that is a healthy sign. If Google selects a different domain or an unrelated URL, treat that difference as evidence that another signal is still out of line.

    If Google selects a different domain or an unrelated URL, do not dismiss it as a reporting quirk. It is a diagnosis. Recheck the page canonical, internal links, sitemap entry, redirect behaviour, and any surviving preview-domain references. The Page Indexing report can also expose blocked pages, soft errors, and cases where Google has chosen a different canonical.

    For the staffing-company pattern, this is where the invisible launch becomes legible. A browser may show the right site, but Search Console can reveal that Google has clustered trust around a different host. That helps explain why a brand-name query yields zero owned pages even though internal teams insist the site is live.

    Request indexing only after the production signals agree. New sites can take time to appear, but waiting is not a strategy when the site is blocked, broken, or declaring the wrong domain as canonical.

    Prove brand-name discoverability

    Run a direct search for the company brand name, both quoted and unquoted. Then run a diagnostic search using site:your-production-domain.com brand name. The immediate objective is simple: establish whether any page from the production domain is appearing for the company’s own identity.

    This is not a vanity check. It is a practical answer to a basic launch question: when someone actively looks for the company, do they reach the company? A healthy result is not necessarily perfect ranking breadth on day one. It is evidence that the production domain has entered the index as the company’s real home.

    Zero owned results is not a normal launch metric to rationalise away. It is a signal to revisit indexing and canonicalisation before investing further in search content or paid distribution. A company should not need to outspend competitors to be found for its own name.

    A modern workspace showing hands analyzing marketing data on a laptop and paper documents.
    A modern workspace showing hands analyzing marketing data on a laptop and paper documents.

    In the staffing-company case, that zero-owned-pages result was not a mystery once the technical signals were reviewed. It was the market-facing symptom of a sitemap and canonical setup that kept naming the preview host, combined with a bare domain that failed at the root.

    Verify measurement, then create a real path into the site

    Confirm that analytics records visits on the production domain. Use a genuine visit from a separate device or network and verify that the visit appears in the correct property. This proves measurement, not discoverability. A working analytics setup can record a handful of direct visits while Google still cannot index the site correctly.

    That distinction matters because founders often see a few sessions and conclude the launch is broadly functioning. It may only prove that people with the exact URL can arrive. It does not prove that search engines understand the site, or that anyone searching the brand will be led to owned pages.

    Then make sure an owned channel links to the live domain. Update founder and employee email signatures, the company LinkedIn page, the existing mailing list, sales decks, proposal templates, directories, job platforms, and relevant procurement profiles. Replace every preview or legacy URL.

    This is where distribution starts. Search visibility compounds over time, but a new launch should not depend on search alone for its first discovery. Owned channels create immediate routes for customers, partners, candidates, and existing contacts — while also reinforcing that the production domain is the place the business intends to send people.

    For teams facing near-zero visitors, this is also the point to check for the “zero owned pages, zero owned links” combination. If search cannot find you and none of your existing channels point cleanly to the new domain, the issue is not weak demand. It is that the routes into the business were never fully connected.

    Where launch teams waste time

    • Refreshing analytics repeatedly: analytics cannot tell you whether canonical tags point to a preview domain.
    • Blaming the site’s age immediately: newness can delay indexing, but crawl blocks, error responses, and wrong canonicals are more urgent explanations.
    • Fixing only the homepage: broken templates can leave service, jobs, resources, or campaign pages invisible even when the homepage looks healthy.
    • Running paid traffic to an uncertain destination: paid clicks do not repair a broken technical handover and can send expensive attention to the wrong host.
    • Leaving legacy and preview links in commercial materials: every outdated link trains partners and prospects to use a destination the company no longer controls.

    These mistakes share the same underlying flaw: they treat discoverability as a promotion problem before it has been validated as an infrastructure problem. In the first hour, the job is not to generate demand. It is to verify that the company has a single reachable, indexable, publicly signposted home.

    The better move: turn launch checks into a distribution system

    The durable answer is not a heroic launch-day scramble. It is a release gate that treats production-domain clarity as a requirement for publishing. Before any major release, confirm the preferred host, redirects, robots directives, sitemap URLs, canonical tags, analytics property, and owned-channel links.

    Give every check a named owner, a trigger, and a next action. If a page returns an error, someone owns the correction. If Google selects the wrong canonical, someone owns the investigation. If a deck still links to a preview URL, someone owns the replacement. Systems outperform memory, especially once a company has multiple campaigns, contributors, domains, and releases in motion.

    That is the wider strategic lesson. Authority is not only what a company publishes. It is also the reliability of the routes that let buyers discover, verify, and return to that company. Content cannot compound when the underlying domain signals are fragmented.

    What a healthy launch looks like

    Done right, the site has a single clear production home. Its redirects, sitemap, canonical tags, internal links, crawl rules, and external links all point to that same destination. Google Search Console sees the intended pages, analytics measures visits to the correct domain, and owned channels give real people a direct route in.

    The essential sequence is straightforward: establish reachability, remove index blocks, correct sitemap and canonical signals, confirm Google’s interpretation, prove brand discoverability, then activate owned distribution. That order prevents the most expensive launch mistake of all: building visibility on top of a site that search engines have been told not to trust.

    If you launched and nobody came, assume nothing. Check whether the market can actually reach the company you think you published. In many cases, as the staffing-company example shows, the site is not failing because demand is absent. It is failing because the business has accidentally told search that it lives somewhere else.

  • Is SEO Dead in 2026? What 20+ Sites Show

    Is SEO Dead in 2026? What 20+ Sites Show

    In March 2026, a travel property we registered earlier that year had 0 Google clicks a week. By mid-August, it had reached 1,587 Google clicks a week. That is not the performance of a dead channel. It is the performance of a discovery system that still rewards useful pages built around real demand.

    We run more than 20 sites across our portfolio, and the question founders raise most often is whether SEO is still worth the effort. Usually, the question arrives after a click plateau, an AI Overview replaces a familiar blue-link result, or a LinkedIn post that would once have travelled gets ignored by the feed. The instinct is understandable: if clicks and reach fall, the business must be becoming less visible.

    That conclusion is often wrong. Visibility has fragmented. Google clicks, Bing clicks, and AI-answer citations now describe different outcomes on different surfaces. A company can be found without receiving a traditional click. It can earn a citation inside an AI-generated answer without receiving a click from that citation. It can gain demand through Bing while its entire reporting culture remains fixated on Google.

    SEO is alive. The single-channel version is dead.

    The plain answer is no: SEO is not dead in 2026. Single-channel SEO is.

    The old operating model was simple enough to become lazy. Publish content, improve rankings, collect Google clicks, call that organic growth. It made sense when search visibility and search clicks were close enough to treat as the same thing. That relationship has broken apart.

    Today, the work is no longer just to rank and earn a click. The work is to rank, get cited, and get found wherever the buyer begins their research. Google remains material. Bing is no longer a side effect. AI answer systems have created a new form of visibility that is real but cannot be dishonestly counted as clicks.

    Founders should take that distinction seriously. The companies that treat declining organic clicks as proof that search is over will retreat from one of the few compounding acquisition systems available to them. The companies that treat every AI citation as if it were a visitor will build dashboards that flatter the team and mislead the business.

    Key takeaways

    • Google Search still produces meaningful growth when a site publishes pages that answer real questions with real usefulness.
    • Bing has become a material acquisition channel, not an afterthought to Google reporting.
    • AI citations are a visibility signal, not clicks, and they must be measured separately from search clicks.
    • The durable strategy is a multi-surface discovery system backed by owned audience data, not a gamble on one algorithm.

    Our own portfolio data makes the argument better than any hot take can

    FinalBoss, one of our own portfolio properties, gives us the clearest view of what is actually changing. Its Google clicks rose from about 490 a week in March 2026 to about 1,050 a week in August 2026. That is not a theoretical argument for search. It is a direct operating result from publishing for questions people are already trying to solve.

    The more revealing result sits beside it. FinalBoss Bing clicks rose from 101 a month to about 3,500 a month. Too many teams still treat Bing as a rounding error because their strategy, reporting, and attention have been trained around Google alone. That is no longer a defensible position. A channel does not become unimportant because a founder has not built the habit of checking it.

    Then there is AI visibility. In June 2026, FinalBoss recorded 3,874 Google clicks, 3,509 Bing clicks, and 112,585 AI citations. Those are separate units. They should stay separate.

    Discovery surface FinalBoss result in June 2026 What the metric means
    Google Search 3,874 Google clicks Clicks recorded from Google Search.
    Bing Search 3,509 Bing clicks Clicks recorded from Bing Search.
    AI answer systems 112,585 AI citations References to the property inside AI-generated answers, not clicks.

    Citations do not equal clicks. They should never be added to Google or Bing click totals. A citation does not tell us where the reference appeared in an answer, how prominently it was presented, whether the user trusted it, or whether it produced any later business outcome. It tells us that the business was present in an answer environment where traditional reporting cannot see the full picture.

    That still matters. Being absent from AI answers is not neutral when buyers increasingly use those answers to narrow a category, frame a problem, compare approaches, or decide which providers deserve further research. Authority is an asset precisely because it changes who gets included when systems summarize the market.

    This is not just an internal reporting quirk. Public webmaster tooling has moved in the same direction. Bing introduced AI Performance in public preview in February 2026 and later added AI Visibility Insights, including Citation Share. That is the market telling founders something important: search visibility and search clicks are no longer the same measurement problem.

    The travel property is the harder evidence founders should care about

    It is easy to dismiss growth on an established property as the advantage of history. The travel property removes that excuse. It was registered in early 2026. It started with 0 Google clicks a week in March and reached 1,587 Google clicks a week in mid-August.

    This matters because founders often assume they are too late. They see large incumbents, AI summaries, crowded result pages, and increasingly volatile social distribution. Then they conclude that a newer property has no path to visibility unless it buys attention forever.

    That is the wrong lesson. New sites can still earn demand. What has become harder is publishing vague material and expecting search engines to manufacture relevance on your behalf. The property did not need a legacy domain to move from zero. It needed pages tied to real search demand and a system capable of producing useful coverage consistently.

    A modern workspace showing hands analyzing marketing data on a laptop and paper documents.
    A modern workspace showing hands analyzing marketing data on a laptop and paper documents.

    This is the distinction between content and distribution. Content is the asset you publish. Distribution is the system that gets the asset discovered through search results, answer systems, platform feeds, direct channels, and referrals. Companies that confuse the two end up producing more content while remaining invisible.

    What AI changed is measurement, not the need to be useful

    AI Overviews and AI answer systems have disrupted the old expectation that visibility automatically turns into a click. A user can receive an answer, see a brand referenced, and leave the search experience without visiting a site. That creates a legitimate concern for publishers and operators who built their model around search clicks.

    But the wrong response is declaring SEO obsolete. The correct response is recognizing that discovery now produces more than one kind of outcome. Bing’s AI visibility reporting reflects this shift directly: it tracks citation-based visibility for AI-generated answers rather than pretending that every appearance is a click.

    That product decision matters because it formalizes what operators need to understand. Visibility and clicks are not interchangeable. A company needs to know when it is earning Google clicks, when it is earning Bing clicks, and when it is being cited in the places where its category is being explained.

    Google has moved in the same general direction. Search Console now gives teams more direct reporting for generative AI search performance, including views by pages, countries, devices, and time. That matters less as a novelty than as a management signal: if the platform gives you a separate lens for AI-feature visibility, your reporting model should stop pretending that one line called organic explains everything.

    We would not advise any founder to celebrate citation volume in isolation. A business cannot pay payroll with a flattering AI visibility report. But dismissing citations because they are not clicks is equally shortsighted. The point is not to replace click measurement with a shinier metric. The point is to stop forcing every form of discovery into a click-only model that no longer describes how people find companies.

    Founders also need to understand what the controls actually do

    One reason the debate gets muddled is that teams keep blending together controls that do different jobs. A robots.txt rule is about crawling. Google-Extended is a separate control related to how Google’s AI systems may use content. The newer Search Console exclusion is narrower and aimed at generative AI features. Those are not interchangeable switches, and founders should stop treating them as if one decision covers every surface.

    That distinction matters operationally because measurement can break before performance does. If a team blocks crawling, it can affect whether pages are discovered and processed at all. If a team changes a generative AI exclusion, it is making a more limited decision about where content may appear in AI-driven experiences. If reporting only looks at sitewide Google clicks afterward, the business may never learn which surface actually changed.

    The shift around Top Stories in AI Overviews makes this more practical than theoretical. The long-running opt-out conversation is no longer just about blue links on one side and AI on the other. Some visibility decisions now sit inside blended AI surfaces, which means founders need to be precise about what they are excluding and what they are trying to preserve.

    Team working on marketing strategy using data charts and papers in an office meeting.
    Team working on marketing strategy using data charts and papers in an office meeting.

    So before changing any exclusion setting, capture a baseline. At minimum, hold onto a fixed 30-day and 90-day view of Google clicks, Google impressions, page-level patterns in Search Console, AI-feature visibility where available, and index coverage for the sections most likely to be affected. If the property has pages that can surface in Top Stories-style environments, measure those sections separately rather than hiding the change inside a sitewide average. Otherwise you will end up debating principles while the only thing you really needed was a clean before-and-after read.

    The SEO practices that deserve to die are the ones built for an older internet

    There is a version of SEO that should die, and founders should be relieved to see it go. It is the version built on publishing generic pages because a keyword tool showed volume. It is the version that mistakes a rank report for a growth strategy. It is the version that treats a blog as a warehouse of interchangeable articles rather than a body of evidence that proves the company understands a problem.

    It is also the version that treats Google as the entire internet. Buyers discover through Google, Bing, YouTube, LinkedIn, Amazon, ChatGPT, TikTok, communities, referrals, and direct recommendations. In some businesses that might mean Google Business Profile matters more than a blog post. In others, Amazon SEO or YouTube search may carry more of the load. The surfaces differ by business, but the strategic principle does not: single-channel growth is fragile.

    For a founder, this is not a call to chase every platform. It is a call to stop making a single platform responsible for the company’s entire visibility. A business should identify the questions that shape demand, build authoritative answers around those questions, distribute those answers through the surfaces that matter, and create a path from borrowed attention to owned audience data.

    The owned part is the part too many teams skip. Search engines and AI systems can change their presentation overnight. Social platforms can reduce reach without warning. An audience you can reach directly is the stabilizer. Discovery creates the opportunity; audience ownership keeps the business from starting over every time a platform rewrites the rules.

    What we would change if we were rebuilding an SEO program today

    We would stop calling the work “blogging” as if the goal were merely to publish. The function is discovery. Every page should have a job: win a Google Search click, appear in Bing, become useful enough to be cited in an AI answer, support a sales conversation, or move a reader into an owned channel.

    We would measure Google clicks and Bing clicks separately, because FinalBoss shows why that distinction matters. A team that only reviewed Google would have missed Bing moving from 101 clicks a month to about 3,500 a month. That is not an analytics footnote. It is evidence that the business was leaving a meaningful discovery surface under-managed.

    We would track AI citations separately from clicks and refuse to inflate performance reports by mixing the two. The 112,585 AI citations FinalBoss recorded in June 2026 are meaningful as visibility. They are not 112,585 clicks. That discipline protects decision-making. It forces the team to ask the right commercial question instead of celebrating an attractive aggregate number.

    Start with three ledgers, not one

    If we were rebuilding from scratch, we would run three distinct measurement ledgers. The first ledger is Google: clicks, impressions, organic CTR, average position, index coverage, and AI-feature visibility in Search Console where available. The second ledger is Bing: clicks from Bing Search, plus Bing’s AI reporting such as citation counts and Citation Share where those views are relevant. The third ledger is AI visibility as its own category: citations and similar appearance-based signals that describe presence inside answer systems without pretending they are clicks.

    That structure matters because it keeps the story honest. If Google clicks are flat, Bing clicks are rising, and AI citations are rising, the answer is not that nothing is working. The answer is that discovery is moving across surfaces. If all three weaken together, you have a different problem. Founders need a reporting model that can tell those cases apart.

    Build baselines before you touch anything

    Most teams change pages first and ask measurement questions later. We would reverse that. Before a major content push, technical cleanup, template change, or exclusion change, set a baseline for fixed windows such as 30 days and 90 days, then compare against the same window when seasonality could distort the picture. The exact reporting stack will differ by company, but the discipline should not.

    At a minimum, we would track current Google click volume, Bing click volume, AI citation visibility where tools provide it, indexed page counts, organic CTR, average positions for the query sets that matter, and conversion rate from organic clicks into the next owned step the business values. We would also segment those numbers by section or template rather than only sitewide averages. A product comparison page, a glossary page, and a location page do not fail for the same reasons, so they should not be managed as if they do.

    Two adults in an office discussing marketing strategy around a round table.
    Two adults in an office discussing marketing strategy around a round table.

    Audit the technical layer like it still matters, because it does

    There is a fashionable temptation to talk about AI as if technical SEO has become optional. It has not. We would still check crawl and index hygiene first: accidental robots.txt blocks, broken canonicals, redirect chains longer than one hop, HTTPS issues, mixed content, XML sitemap accuracy, and whether the pages we care about are actually reconciling with what Search Console shows as indexed.

    We would also look at server-log behavior where available, because bot activity still tells you whether a search engine is finding, revisiting, or deprioritizing important sections. That is less glamorous than debating AI Mode on social media, but it is often where avoidable losses hide.

    Page experience remains part of the operating discipline as well. Core Web Vitals should be reviewed from field data in Search Console, not only from lab tests. Lab tools such as PageSpeed Insights or Lighthouse are useful for diagnosis, but field data tells you what users actually experience. The current thresholds are concrete enough to manage: Largest Contentful Paint under 2.5 seconds, Interaction to Next Paint under 200 milliseconds, and Cumulative Layout Shift under 0.1. If those numbers deteriorate on key templates, the fix is not abstract “UX work.” It is a measurable performance problem.

    Audit content for usefulness, not volume

    We would also audit existing content for whether it answers a real question better than the alternatives. Not whether it contains the right phrase a sufficient number of times. Not whether it can be produced cheaply by an AI writer. Whether it contributes something useful enough to earn discovery repeatedly across multiple surfaces.

    In practice, that means reviewing pages for intent alignment, freshness, depth, and evidence. Does the page answer the question the searcher actually had? Is it current enough to deserve trust in 2026? Does it offer substance beyond what every other page says? Does it help a buyer compare options, understand tradeoffs, or take a next step? Those questions matter more now because AI systems are good at compressing generic explanations. Generic content no longer enjoys the old advantage of existing at all.

    Set a cadence and a prioritization order

    We would run weekly lightweight monitoring, monthly section reviews for faster-moving properties, and quarterly full audits for most sites. Weekly checks are for sudden regressions: indexing errors, major drops in clicks, or Core Web Vitals deterioration on important templates. Monthly reviews are for patterns: which sections gained or lost visibility, which templates weakened in CTR, which pages stopped matching demand. Quarterly audits are for the larger decisions: architecture, content overlap, exclusions, and where the next round of effort should go.

    We would prioritize fixes in that order too. First, anything that stops pages from being crawled, indexed, or served properly. Second, anything that materially degrades page experience or trust. Third, pages that target real demand but underperform because the answer is weak, outdated, or poorly structured. Only after those basics would we spend time polishing dashboards or arguing about whether SEO itself still exists.

    The companies that win this next phase will not be the ones publishing the most. They will be the ones building the clearest systems for turning expertise into discoverable assets, then turning borrowed discovery into an audience they own.

    The verdict

    SEO is still one of the strongest compounding growth systems available to a company that has built something worth finding. Our portfolio data is blunt on that point: FinalBoss grew Google clicks from about 490 a week in March 2026 to about 1,050 a week in August, while the travel property moved from 0 Google clicks a week to 1,587 a week in mid-August after being registered earlier in the year.

    What died is the comforting idea that one ranking system, one click report, and one platform can explain visibility. Modern discovery is distributed. Google clicks matter. Bing clicks matter. AI citations matter differently. Owned audience data matters because every external platform remains rented ground.

    Founders should not abandon SEO. They should abandon the smaller definition of SEO that made them dependent on one channel in the first place. Visibility compounds when it is treated as a business function, not a marketing side project.

  • How We Would Audit a Blog Producing No Pipeline: We Deleted 79 Posts

    How We Would Audit a Blog Producing No Pipeline: We Deleted 79 Posts

    A blog that produces no pipeline does not need another publishing sprint. It needs a harder decision: which pages still deserve to represent the company in search, and which pages are making the site less useful, less focused, and harder to trust.

    That was the decision behind our own audit. We reviewed 93 posts. We kept 14. We removed 79.

    This was not a cosmetic tidy-up, and it was not an attempt to manufacture a neat before-and-after SEO story. The results on traffic, rankings, and pipeline are still TBD. We are not going to claim that deleting content creates a guaranteed lift before the evidence exists.

    What we can say now is that the blog is no longer trying to be useful to everyone for everything. It has a clearer job: support the themes where we want authority, help the right people discover us, and move them toward something commercially relevant.

    The strategic call: shrink the archive before you scale it

    The common reaction to a blog that is not producing pipeline is more content. More keywords. More publishing cadence. More briefs handed to a team already maintaining pages nobody can defend.

    We would do the opposite first. We would reduce the archive until every surviving page has a strategic reason to exist.

    This is not an argument against content. It is an argument against treating content volume as a distribution strategy. A large archive of generic, overlapping, outdated, or off-topic posts does not create authority simply because it is large. It creates more pages to maintain, more possible dead ends for prospects, and more noise around the themes the business actually wants to own.

    Visibility compounds when the company is consistently associated with a small set of meaningful ideas. It does not compound because the site has accumulated years of loosely related articles.

    Our audit was designed to make that distinction practical. The objective was not to preserve every page that had once been published. The objective was to create a sharper discovery system.

    Set the audit goal before opening the spreadsheet

    The spreadsheet is where most content audits go wrong. Teams export a long URL list, add performance columns, then start debating individual posts without agreeing on what the blog is meant to do.

    That produces the usual outcome: a vague “refresh” backlog, a long list of pages nobody owns, and an archive that stays almost exactly as unfocused as it was before.

    We would define the goal in business terms before reviewing a single URL:

    • Clarify the core themes the company wants to be known for.
    • Remove pages that dilute those themes or compete with stronger pages.
    • Create cleaner paths from discovery to the company’s higher-intent pages.
    • Stop spending editorial effort maintaining content with no meaningful role.
    • Make future publishing decisions against a higher bar.

    The goal should not be “save as much content as possible.” It should not be “increase traffic at any cost.” And it should not be “make the dashboard look healthier.”

    A blog is part of the company’s distribution infrastructure. Its job is to help the market discover the business, understand its authority, and take a useful next step. If a post does none of those things, preserving it because it exists is not prudent. It is inertia.

    Team reviewing a content audit with keep/kill color cues.
    Team reviewing a content audit with keep/kill color cues.

    Business goal → core themes → page role → keep or remove

    Build an inventory that supports decisions, not reporting

    Tools are useful here, but they are not the strategy. Google Search Console, Google Analytics, and Screaming Frog can help establish the inventory and surface evidence. None of them can decide whether a page deserves to remain part of the company’s public point of view.

    For each post, we would capture only the information needed to make a real decision:

    • The URL and the page’s actual topic.
    • The core business theme it is meant to support.
    • The search intent or discovery role it serves.
    • The page it overlaps with, if it targets a similar idea.
    • Its performance signals from Google Search Console.
    • Its engagement and conversion context from Google Analytics.
    • The next meaningful destination available to the reader.
    • A final keep-or-remove decision with a written reason.

    The important phrase is written reason. A page should not survive because someone says it might become useful someday. If the team cannot explain why it belongs in the business’s future distribution system, the page has not earned a place.

    Do not turn this into a vendor comparison or a tooling project. Screaming Frog can help identify the surface area. Google Search Console can show how people find the page. Google Analytics can show what happens after they arrive. The judgment still belongs to the operator running the business.

    The keep-or-kill bar we used

    We did not create a broad “update everything” category. That category is often where weak content goes to avoid a decision. It sounds responsible, but it usually becomes a warehouse for pages that nobody will meaningfully improve.

    Every surviving page had to clear a simple bar:

    Core theme → distinct purpose → credible authority → meaningful next step

    If a page could not clear that bar, we removed it. That is how a review of 93 posts became 14 retained posts and 79 removed posts.

    A page earned a keep decision when it did all four jobs

    • It supported a core theme. The topic had to reinforce what we want the company to be known for. A page can be well written and still be strategically irrelevant.
    • It had a distinct purpose. The page needed a clear reason to exist alongside every other surviving post. Similar pages targeting the same idea create unnecessary competition and confuse the site’s topical structure.
    • It could build authority. The post needed to demonstrate useful judgment, not simply restate information that could be generated, summarized, or answered elsewhere without the company’s expertise.
    • It led somewhere meaningful. A reader needed a logical next step. That does not mean every page needs an aggressive sales message. It means the page cannot leave the visitor in a generic content loop with no connection to the business.

    The 14 posts we retained were not selected because we were emotionally attached to them or because removing content feels uncomfortable. They survived because they could still contribute to a focused body of work.

    A page earned removal when it weakened the portfolio

    • It covered a topic outside the company’s strategic territory.
    • It repeated or competed with a stronger page on the same subject.
    • It was generic enough that it added little original authority.
    • It sent readers into an outdated, unclear, or commercially irrelevant journey.
    • It existed because a keyword was available, not because the company had a reason to own the conversation.

    The mistake we see most often is treating deletion as an extreme measure. It is not. Deleting weak content is normal portfolio management. The extreme move is continuing to publish into an archive that nobody believes in.

    Resolve overlap before judging posts in isolation

    Content cannibalization is rarely obvious when reviewing one URL at a time. Each article can look reasonable on its own. The problem becomes clear when several posts are trying to answer the same underlying question, rank for the same type of query, or occupy the same place in the buyer journey.

    Audit framework mapping content actions to pipeline impact.
    Audit framework mapping content actions to pipeline impact.

    When that happens, the right response is not to preserve all of them and make minor edits. We would decide which page should become the single authoritative resource, then remove the weaker leftovers from the editorial portfolio.

    This matters for two reasons. First, multiple overlapping posts can split attention, internal authority, and external signals across pages that should not be competing. Second, it creates a poor reader experience. A prospect who lands on three versions of the same broad article does not gain confidence in the company. They lose time.

    Cleaner content architecture creates cleaner journeys. That is not a cosmetic SEO exercise. It is a business outcome. The fewer irrelevant detours a high-intent visitor encounters, the more likely they are to reach content that helps them evaluate the company properly.

    Use performance data as evidence, not as the decision-maker

    A post with traffic is not automatically a keeper. A post with low traffic is not automatically a removal.

    Google Search Console can show whether a page earns search visibility and the kinds of queries connected to it. Google Analytics can provide context around what visitors do next. Those are useful signals. But neither replaces the strategic question: does this page help the company own a topic that matters?

    A high-traffic article can still be a poor asset if it attracts the wrong audience, leads nowhere relevant, and weakens the company’s topical focus. A quieter post can be worth retaining if it demonstrates real expertise on a core theme and supports a valuable discovery path.

    The anti-content-mill standard is simple: do not keep a page merely because it can attract attention. Keep it because the attention strengthens authority, distribution, or pipeline.

    That distinction becomes more important as AI Overviews and AI Mode change how informational searches are resolved. Generic explanatory content has a weaker role when the search journey can end with a synthesized answer. The pages worth protecting need a clearer reason to be chosen, remembered, and acted on.

    Do not refill the archive with more generic articles

    Removing 79 posts creates a temptation to restore the old volume as quickly as possible. That would miss the point.

    The next content plan should be more selective than the last one. Every new page needs a defined role in the company’s discovery system before it is commissioned. If it does not reinforce a core theme, create useful authority, or lead the right reader toward a meaningful next step, it does not belong in the plan.

    Deleting low-impact posts as part of the audit workflow.
    Deleting low-impact posts as part of the audit workflow.

    The advanced move is to look beyond purely informational articles where the business has a genuine utility advantage. Free, single-purpose tools can win durable SEO traffic, especially as AI responses reduce demand for generic informational content. A useful tool is not a loophole for publishing more assets. It must still serve a specific problem, reinforce a core topic, and fit the company’s broader distribution strategy.

    That is the broader lesson: content is not the asset. The asset is a system that makes the company easier to discover, easier to trust, and harder to ignore.

    Troubleshooting the decisions that usually stall an audit

    The team wants to keep everything “just in case”

    This is the most common failure point. “Just in case” is not a role. It is a refusal to prioritize. Return to the original goal and require a clear explanation of how the page supports visibility, authority, discovery, or pipeline.

    If the explanation is hypothetical, the page has not earned retention.

    A page has traffic but no business relevance

    Do not let traffic alone override strategy. A large audience that will never become the right audience can consume editorial resources while distracting the company from topics it should own. The question is not whether a page can be found. The question is whether being found for that page makes the company stronger.

    Several posts are similar, but nobody wants to choose a winner

    Choose the page that best represents the future authority you want to build. Do not preserve every variation to avoid conflict. A domain becomes clearer when it has one strong answer for a subject instead of several partial answers competing for the same attention.

    Leadership expects immediate proof that the deletions worked

    Be direct: the immediate achievement is a more coherent portfolio, not a fabricated performance win. Our own results are TBD. The right standard is to observe what happens after the business has created a cleaner content system, not to attach invented causality to the act of removing pages.

    What done right looks like

    A successful audit does not end with a shorter spreadsheet. It ends with a blog where every surviving post has a defensible purpose and every future idea faces a higher standard.

    For us, that meant reviewing 93 posts, retaining 14, and removing 79. It meant accepting that deletion is part of building authority. It meant refusing to mistake an oversized archive for a distribution advantage.

    The result we are building toward is not simply more content performance. It is a stronger discovery system: fewer distractions, clearer topical authority, better paths for serious prospects, and a content operation that supports the business rather than merely producing output.

    TL;DR

    • Audit a blog against business goals before reviewing individual URLs.
    • Treat content as distribution infrastructure, not an inventory that must be preserved.
    • Use Google Search Console, Google Analytics, and Screaming Frog for evidence, not judgment.
    • Keep only pages that support a core theme, have a distinct role, build authority, and offer a meaningful next step.
    • Remove off-topic, generic, overlapping, outdated, and commercially disconnected posts.
    • Do not use deletion as a shortcut to claim SEO results. Our results remain TBD.
    • Use the cleared capacity to build fewer, stronger assets that improve discovery and authority.
  • Your Dashboard Measures the Channel That’s Dying—and Ignores the One Growing

    Your Dashboard Measures the Channel That’s Dying—and Ignores the One Growing

    Across the companies we study, the most dangerous dashboard problem is not bad data. It is a perfectly tidy dashboard answering the wrong question with great confidence. The clearest break came into view in June 2026 on one property: 112,585 AI citations and 3,874 Google clicks in the same month.

    Those are not competing versions of the same metric. They are explicitly different units. AI citations measure instances in which the property was surfaced in AI-generated answers. Google clicks measure recorded visits from Google Search. One is a visibility signal. The other is an acquisition signal. Neither can be divided by the other to produce a meaningful conversion rate, and neither proves the commercial value of the other on its own.

    But that gap exposes the problem every marketing leader reporting to a CEO or board now has to confront: the dashboard still privileges the click, even as an increasing share of discovery happens before, around, and without one. We are using a measurement model designed for the ten-blue-links era to judge a discovery environment that has changed underneath it.

    The dashboard is not broken. Its definition of marketing is obsolete.

    For years, traffic was a reasonable shorthand for whether content was working. A person searched, saw a result, clicked, landed on a site, and entered an analytics system with a referrer attached. It was never perfect, but it was legible enough to support budget decisions.

    That journey is no longer the default. Google AI Overviews, AI Mode, ChatGPT, Perplexity, Claude, Bing Copilot, mobile interfaces, copied answers, and zero-click behavior have inserted new layers between a company’s expertise and the visit its dashboard can recognize. The old model records the final handoff. It misses much of the influence that happened before it.

    This matters because a board dashboard does more than report performance. It determines what gets funded, what gets cut, and which teams are told to “focus on what works.” If the dashboard can only see clicks, the business will systematically overvalue work that produces trackable sessions and undervalue work that earns discovery inside the interfaces customers increasingly use to make decisions.

    Key takeaways

    • Traffic is no longer a complete proxy for content value. AI-mediated discovery can create awareness and consideration without producing a recognizable referral session.
    • AI citations and Google clicks must stay separate. Citations are visibility signals; clicks are visits. Blending them creates false precision.
    • “Direct” is increasingly an unresolved bucket, not a clean source category. Mobile apps, copied URLs, and generative search journeys can erase the referrer before the session reaches analytics.
    • Discovery needs its own measurement layer. Boards should see AI visibility, identifiable AI-assisted visits, unknown/direct arrivals, and on-site business outcomes as distinct parts of one system.

    The click is shrinking as the default proof of discovery

    The numbers make the direction hard to ignore. In the first four months of 2026, 68% of U.S. Google searches ended without a click. That is not a small tracking anomaly. It is a structural change in how people use search.

    When a Google AI Overview appears, click-through rate falls by nearly 60%. Only about 1% click a link within the AI Overview itself. A conventional traffic dashboard interprets this as a simple verdict: the page lost demand, the topic is less valuable, or the content failed.

    That interpretation is often lazy. A user may have received enough of an answer to leave without clicking. They may have seen a company named, cited, or framed as an authority and then returned later through another route. They may copy a URL from an AI interface, type a company name into a browser, or come back through a bookmarked page. The company can participate in the decision while receiving none of the session-level credit.

    ChatGPT referrals grew 206% in 2025 in clickstream analysis covering 17 months of U.S. data. That is meaningful, but it is still only the visible portion: the sessions where a referral survives and is passed through. Treating referral growth as the full AI channel is the same error as treating recorded clicks as the full value of organic search. It confuses what is observable with what is happening.

    Conceptual visual contrast between dying click-based traffic and growing AI citation visibility.
    Conceptual visual contrast between dying click-based traffic and growing AI citation visibility.

    We should be clear about the conclusion. This does not mean traffic no longer matters. It means traffic is now a narrower measure than the content strategy it is being asked to judge.

    “Direct” has become a graveyard for attribution

    The attribution problem becomes more severe on mobile. People frequently use AI assistants inside mobile apps, where referrer headers can be stripped before the session reaches a website. What began as an AI-influenced journey arrives in analytics as Direct.

    Copy-and-paste behavior creates the same outcome. Someone receives an answer, copies a company URL, opens a browser, and visits directly. No conventional source record connects that visit to the AI response that created it. The dashboard records a direct session and tells a neat but incomplete story.

    Google AI Overviews create another blind spot. A company can be visible in the answer, influence the user’s understanding, and still receive neither a click nor an attributable session. That influence does not become less real because GA4 has no referrer to assign.

    The worst response is to relabel every direct visit as AI traffic. That is not measurement; it is wishful attribution. Direct remains an unknown bucket containing many paths. The disciplined response is to acknowledge the gap, preserve it in reporting, and stop pretending that a low-click journey has no commercial relevance simply because its influence cannot be assigned with the old rules.

    The June 2026 gap is a warning, not a vanity metric

    Return to the June 2026 example: 112,585 AI citations versus 3,874 Google clicks on one property. The temptation is to frame that as an extraordinary ratio or to declare that AI citations are “worth” a particular number of clicks. That would be a category error.

    How AI traffic gets misattributed in legacy dashboards and isolated in updated reporting.
    How AI traffic gets misattributed in legacy dashboards and isolated in updated reporting.

    A citation is not a visitor. It does not tell us whether the cited answer was read closely, trusted, remembered, or converted into a commercial action. A Google click is not the complete value of a page either. It tells us that a visit occurred, not whether the visitor discovered the brand for the first time, whether they had encountered it earlier in an AI answer, or whether the page built authority that will shape future discovery.

    The value of the June figures is not that they create a new winner-takes-all KPI. Their value is diagnostic. They show that the company’s visible presence in AI answers was vastly larger than the portion of Google traffic the conventional dashboard used as its primary proof of discovery. A board that sees only 3,874 clicks is not seeing the whole commercial environment.

    This is the central operating lesson: visibility compounds before attribution catches up. Companies that are repeatedly cited become easier to encounter, easier to recognize, and more likely to be considered. The analytics system may show only fragments of that process. The market does not wait for a clean referrer before it forms an opinion.

    What we would instrument instead

    The answer is not a new vanity dashboard and not an attempt to force every AI interaction into a fake channel report. It is a measurement architecture that separates discovery from acquisition and treats uncertainty honestly.

    • AI citation visibility. Record when and where the company’s property is cited in AI-generated responses. This is a discoverability measure, not traffic and not revenue. Its purpose is to show whether the company is present in the answers shaping a category.
    • Identifiable AI-assisted visits. Segment sessions that do retain a recognizable AI-assistant source. These are useful acquisition signals, but they should be reported as the attributable portion of AI-mediated discovery, not as the whole channel.
    • Direct and unknown arrival paths. Keep direct traffic visible as unresolved rather than silently treating it as proof that a user arrived without influence. It is important to preserve the uncertainty instead of assigning credit that the data cannot support.
    • On-site business outcomes. Measure the commercial actions that occur on the company’s own property after arrival. The relevant action will differ by business, but it should remain separate from the visibility layer and the referral layer.
    • Content-level discovery patterns. Connect cited pages and topics to identifiable visits and on-site outcomes without pretending every citation led directly to a session. The goal is not a mythical single metric. The goal is a more accurate decision system.

    This structure prevents a common reporting mistake: using the same metric to assess every stage of growth. Citations answer whether the business is being surfaced. Referrals answer whether a source passed a visitor through. On-site outcomes answer whether an arrival did something that matters. These are related, but they are not interchangeable.

    There is also a reporting break that leaders need to handle carefully. From May 13, 2026, new ai-assistant medium values allow traffic from assistants such as ChatGPT, Perplexity, Claude, and Bing Copilot to be segmented separately from Referral or Direct. That is useful for future reporting. It is not retroactive. Sessions before that point remain classified under their earlier labels, which means default month-on-month comparisons can create a false story in which AI traffic suddenly appeared from nowhere.

    It did not appear from nowhere. The dashboard simply gained a better label for a portion of traffic it had previously misclassified.

    Illustrate the metric-unit shift from clicks to citations.
    Illustrate the metric-unit shift from clicks to citations.

    Boards should stop asking content to prove itself with one number

    A CEO or board does not need a lecture on referrer headers. They need a decision-grade view of how the business earns discovery, turns discovery into visits where possible, and converts identifiable demand on its own property.

    That changes the conversation. Instead of asking why a page lost clicks after an AI Overview appeared, leadership can see whether the company is still being surfaced in the category, whether identifiable AI-assisted traffic is growing, what share of arrivals remains unknown, and whether the business is generating outcomes once people reach an owned destination.

    This is not softer measurement. It is stricter measurement. It refuses to claim that a citation equals a sale. It also refuses to claim that an uncredited journey had no value. Both forms of overconfidence lead to bad allocation decisions.

    The companies that win this shift will not be the ones obsessing over a new source label in a weekly traffic report. They will be the ones building a durable discovery system: content and product information structured well enough to be surfaced, authority strong enough to be cited, and owned destinations capable of turning attention into a relationship and an outcome.

    TL;DR

    Your traffic dashboard is still useful, but it is no longer a complete map of how customers discover a company. AI Overviews, AI assistants, mobile apps, copied links, and zero-click behavior have weakened the connection between influence and the referral data GA4 receives.

    In June 2026, one property generated 112,585 AI citations and 3,874 Google clicks. Those are different units and should remain different units. The lesson is not to replace traffic with citations. The lesson is to stop using traffic as the sole verdict on whether content, authority, and discovery are working.

    Discovery is now a business function, not a line item in an acquisition report. Measure visibility, identifiable visits, unknown paths, and on-site outcomes separately. The businesses that do will make better decisions while everyone else keeps optimizing a dashboard built for the channel that is fading.